Faculty Dr Sivarama Prasad Tera
Dr-Sivarama-Prasad-Tera

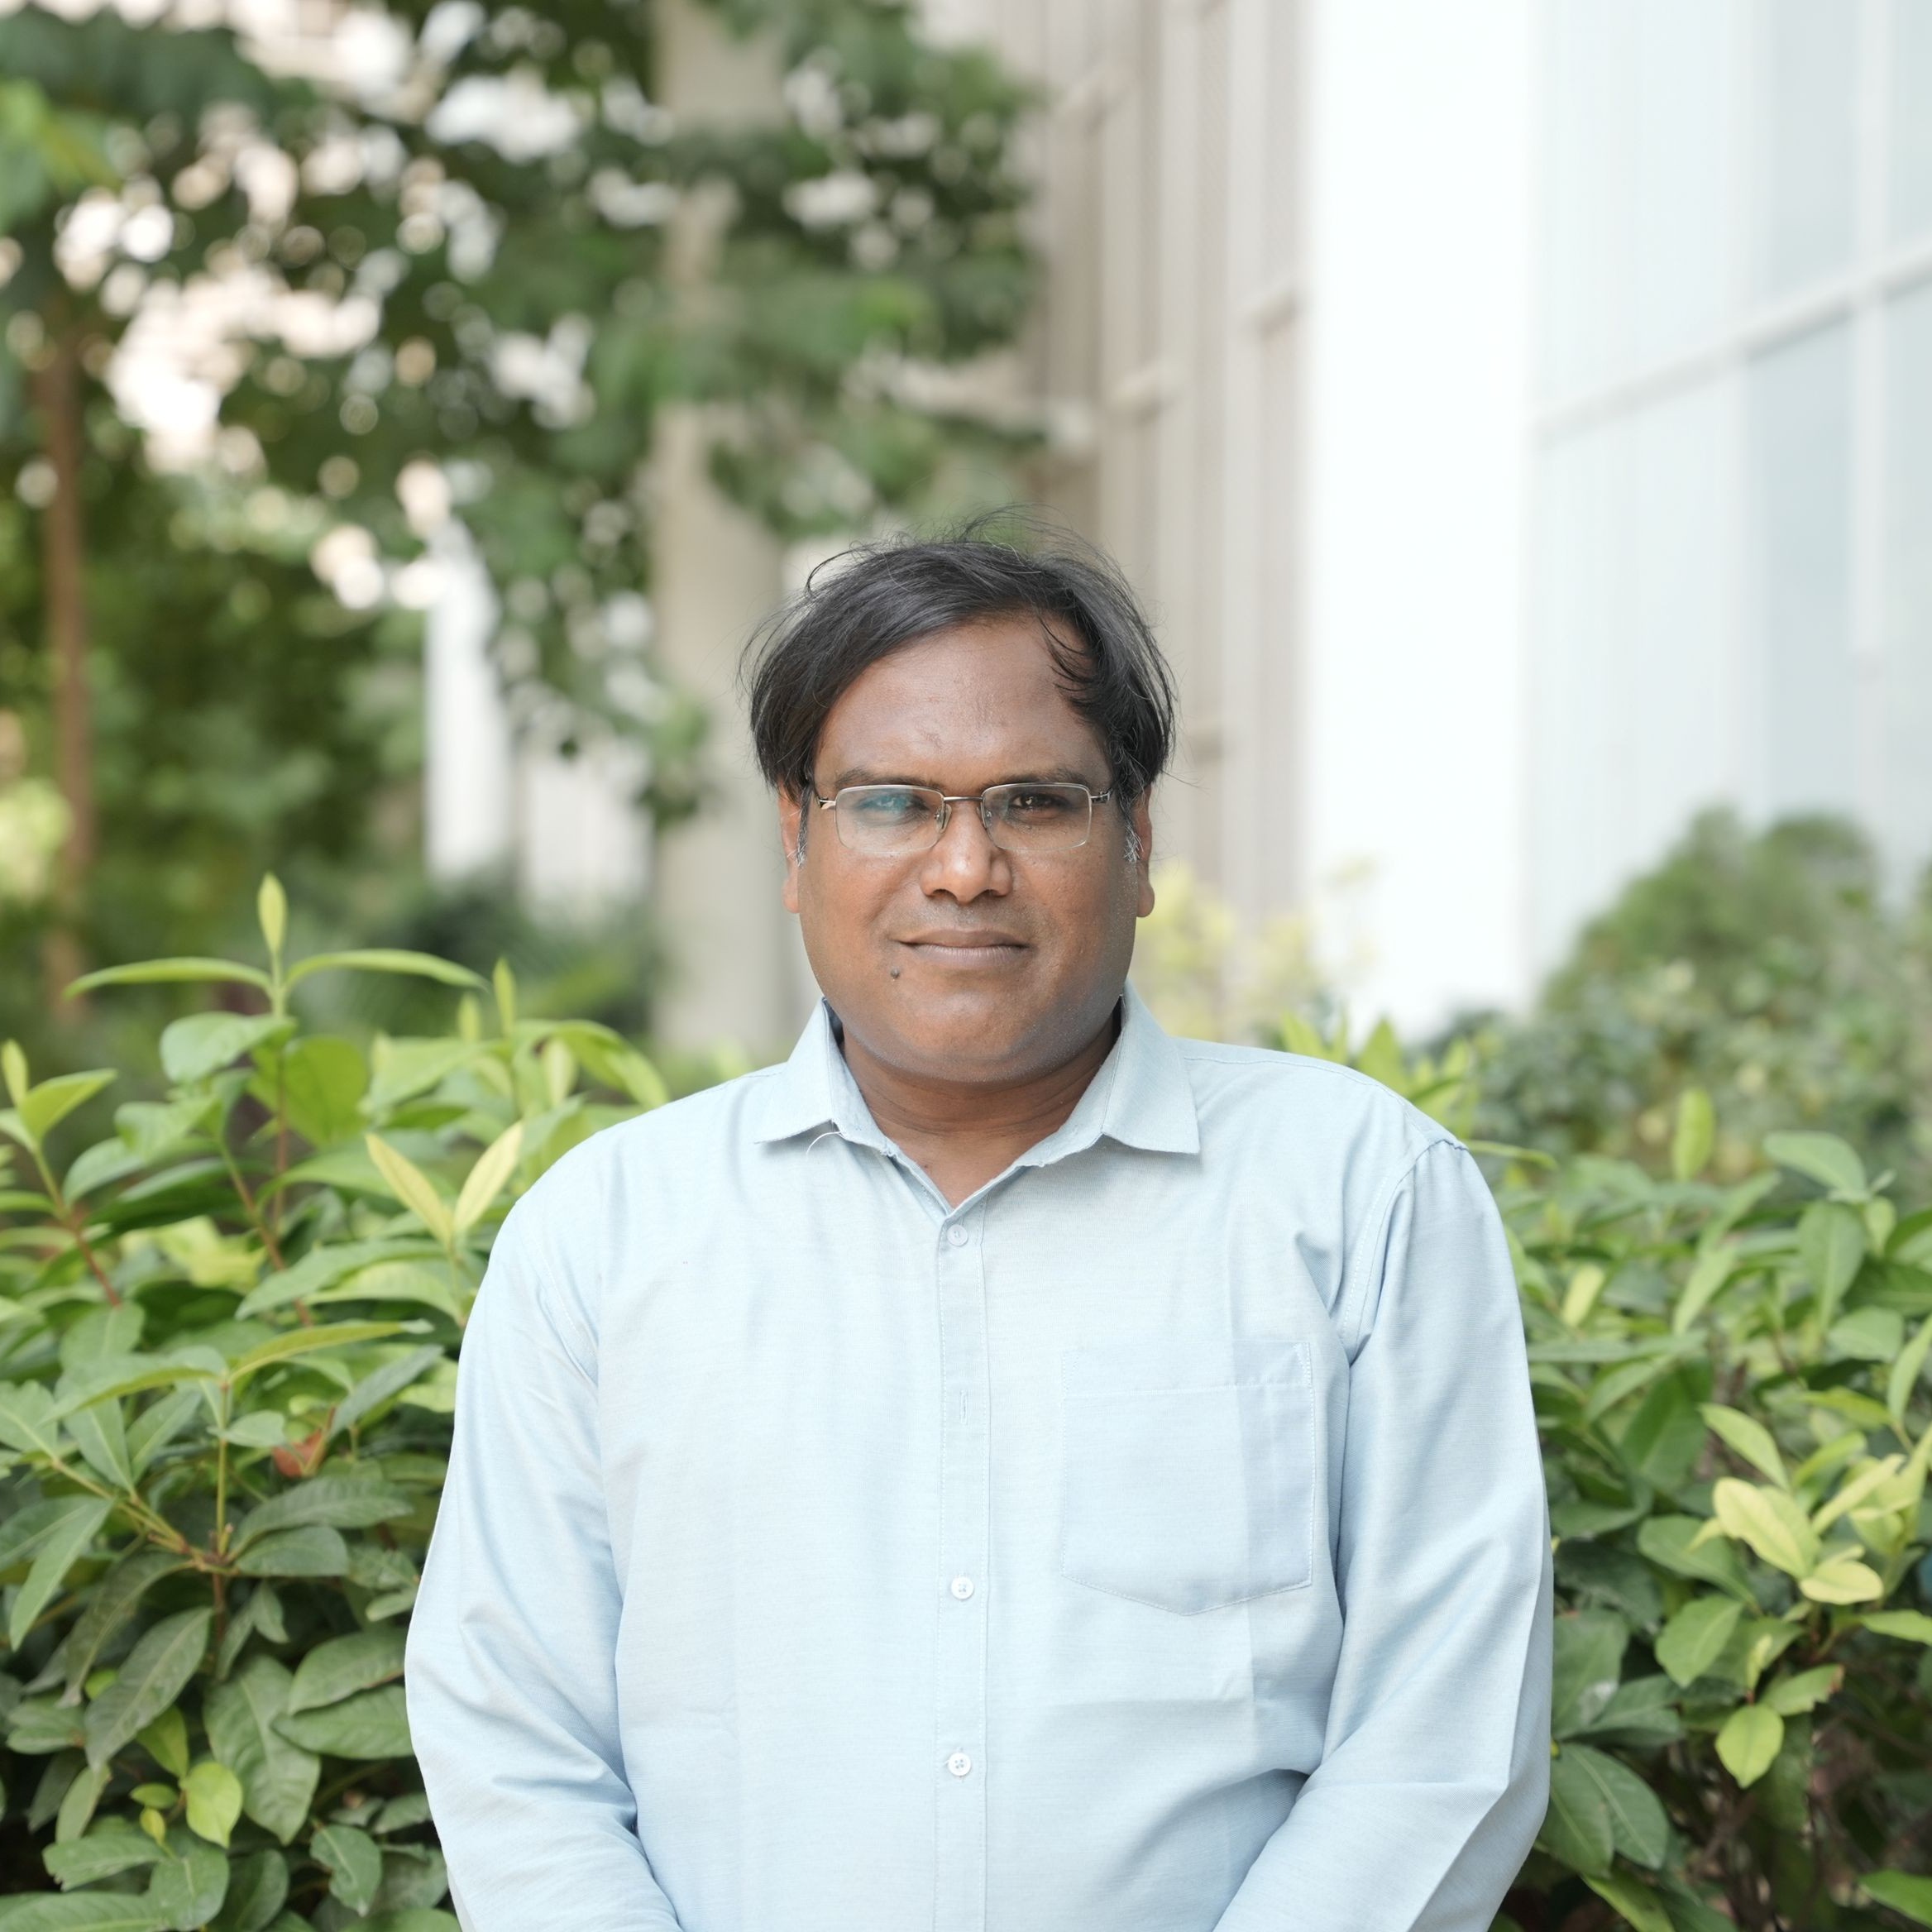
Dr Sivarama Prasad Tera

Assistant Professor

Department of Electronics and Communication Engineering

Contact Details

sivaramaprasad.t@srmap.edu.in

Office Location

Social Links

Education

2025
Ph.D.
IIT Guwahati, Assam
India
2004
M.Tech
MNNIT Allahabad, Uttar Pradesh
India
2001
B.Tech
JNTU KAKINADA, Andhra Pradesh
India

Personal Website

Experience

  • Assistant Professor, ECE, KLUniversity, Andhra Pradesh

Research Interest

  • 6G 5G Channel Decoders, FPGA and ASIC Implementations
  • Machine Learning, Generative AI

Memberships

Publications

  • A Scalable Ensemble Learning Framework for Accurate and Equitable Global Life Expectancy Prediction

    Chinthaginjala R., Tera S.P., El-Shafai W., Azar A.T., Kamal N.A.

    Conference paper, 2026 International Conference on Control, Automation and Diagnosis, ICCAD 2026, 2026, DOI Link

    View abstract ⏷

    Life expectancy prediction using machine learning can support public health planning and policy making, yet practical guidance on selecting among ensemble methods for population-level modeling remains limited. This study evaluates four ensemble regressors, Random Forest, XGBoost, LightGBM, and Gradient Boosting, for global life expectancy prediction under a unified experimental protocol. We use a dataset of 22,050 observations from 195 countries with 149 health and socioeconomic indicators. Models are tuned via extensive hyperparameter search with stratified cross-validation, and computational efficiency is assessed alongside predictive accuracy. Performance is reported using the coefficient of determination (R2), root mean squared error (RMSE), and mean absolute error (MAE), both overall and stratified by country income group. XGBoost achieves the highest test accuracy (R2 = 0.9943, RMSE = 0.7386 years, MAE = 0.4448 years), outperforming Gradient Boosting (R2 = 0.9908), LightGBM (R2 = 0.9860), and Random Forest (R2 = 0.9856). Performance remains strong across income strata, although lower accuracy in low- and lower-middle-income settings suggests heterogeneous predictability across development contexts. Overall, XGBoost provides the best accuracy-efficiency trade-off under the adopted country-year split, while country-held-out and temporal validation are required before claiming full out-of-country generalization.
  • An Interpretable and Resource-Efficient Machine Learning Framework for Diabetes Detection Under Class Imbalance

    Chinthaginjala R., Tera S.P., El-Shafai W., Azar A.T., Kamal N.A.

    Conference paper, 2026 International Conference on Control, Automation and Diagnosis, ICCAD 2026, 2026, DOI Link

    View abstract ⏷

    Diabetes mellitus is a major global health challenge, motivating reliable early-detection tools for timely intervention. This paper provides a comparative evaluation of traditional machine learning models, Logistic Regression, Support Vector Machines (SVM), Random Forest, and K-Nearest Neighbors (KNN), for diabetes prediction on the DiaBD dataset (5,288 patient records from Bangladesh). To address the pronounced class imbalance (6.5% diabetic vs. 93.5% non-diabetic), we apply the Synthetic Minority Over-sampling Technique (SMOTE) to the training data and assess performance using accuracy, precision, recall, F1-score, and ROC-AUC. Experimental results show that Random Forest yields the best overall performance after SMOTE, achieving 93.67% accuracy and 0.8798 ROC-AUC, outperforming the remaining traditional baselines. Feature-importance analysis further indicates that hypertension, glucose-related measures, and blood pressure are the most informative predictors. These findings support the practical use of traditional, interpretable machine learning models for diabetes risk assessment in resource-constrained healthcare settings.
  • A multi-stage stacking framework for accurate and interpretable life expectancy modeling

    Chinthaginjala R., Tera S.P., Natha P., Srinivasulu A., Al-Turjman F., Mohammad F.

    Article, PLOS One, 2026, DOI Link

    View abstract ⏷

    Accurate life-expectancy estimation is critical for evidence-based health policy, monitoring Sustainable Development Goal 3 (SDG 3), and guiding global resource allocation. Existing machine-learning approaches typically provide point predictions with limited interpretability and uncertainty quantification. To address these limitations, we propose NEXUS-LE (Neuro-Symbolic Explainable Unified Stacking for Life Expectancy), a unified ensemble framework that integrates predictive accuracy, calibrated uncertainty, and policy-level explainability. The model is trained on a global dataset comprising 22,050 country-year observations across 193 countries (2000-2021) and 150 World Health Organization indicators. The framework combines leave-one-out encoding, principal component analysis, and K-Means-based manifold features with SHAP-guided polynomial expansion and a three-level stacking architecture, followed by a LightGBM residual correction and split-conformal calibration. On a held-out test set (n = 3,308), the model achieves R2 = 0.9878, RMSE = 1.0665 years, MAE = 0.6185 years, and MAPE = 0.9239%. Conformal prediction attains 95.04% empirical coverage at the 95% nominal level with a 90% interval width of 3.32 years. Interpretability analysis shows that demographic and structural factors contribute 96.3% of total attribution, with consistent non-linear effects across policy domains. The proposed framework provides a reliable and interpretable solution for life-expectancy prediction in global health applications.
  • Advancing quantum machine learning from conceptual design to practical use

    Tera S.P., Chinthaginjala R., Zhao X., Hamdi M.

    Review, Expert Systems with Applications, 2026, DOI Link

    View abstract ⏷

    This study presents an integrated assessment of quantum machine learning (QML) that combines quantum-computing foundations, algorithmic design, hardware constraints, and empirical evidence into a single, coherent framework. Drawing on a PRISMA-compliant systematic review of 142 peer-reviewed articles published between 2016 and 2025, the study analyzes how QML methods are actually performing on current noisy intermediate-scale quantum (NISQ) devices and against well-tuned classical baselines. A seven-dimensional taxonomy is introduced that organizes the QML design space along data encoding, model paradigms (QSVM, QPCA, QNN, VQC, QBM), training and optimization, hardware platforms, application domains, evaluation protocols, and technology-readiness levels, with method-selection guidelines for each axis. For the five core QML model families, the survey provides end-to-end workflows and comparative evidence tables reporting datasets, hyperparameters, resource usage (qubits, circuit depth, shots, wall-clock time), performance metrics with uncertainty, and explicit advantage classifications. The results show that, under fair comparisons with optimized classical methods and full resource accounting, QML currently yields parity at best—and often classical superiority—for supervised learning on classical data, while the most credible near-term benefits arise in quantum-native domains such as quantum chemistry and many-body physics. The study further proposes an eight-criterion quantum-advantage evaluation framework and a challenge taxonomy that quantify key obstacles—including decoherence, barren plateaus, data-loading overhead, classical competition, and scalability limits—and outline realistic pathways toward future fault-tolerant, quantum-native QML applications.
  • Hybrid AI and semiconductor approaches for power quality improvement

    Chinthaginjala R., Srinivasulu A., Agrawal A., Kim T.H., Tera S.P., Ahmad S.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    This research presents a novel approach to improving electric power quality using semiconductor devices by integrating Machine Learning (ML), Deep Learning (DL), and advanced control strategies. The research addresses key power quality challenges - including voltage sags, swells, harmonics, and transient disturbances - through a data-driven framework that combines traditional control techniques with adaptive learning models. A variety of algorithms, including Support Vector Machines (SVM), Random Forests, Neural Networks, Convolutional Neural Networks (CNN), and Long Short-Term Memory (LSTM) networks, were tested using real-time data. The results showed notable differences in performance, with deep learning models, especially LSTM, proving to be more accurate and dependable in identifying and forecasting power quality issues. In contrast, traditional ML models like SVM and Random Forest had difficulties with class imbalance, resulting in lower precision and recall. DL models, however, managed these challenges effectively, with CNN achieving a precision of 91.8% and LSTM attaining perfect accuracy (100%) and a recall of 94.5%. The study also highlighted the complications of handling imbalanced datasets, as indicated by classification warnings, emphasizing the importance of improved preprocessing and model adjustments for reliable predictions. The execution times varied significantly, with traditional control systems being faster but less capable in identifying complex patterns compared to the computationally intensive DL models. These findings highlight the promise of hybrid systems that integrate both traditional and data-driven control strategies to achieve adaptive and dependable power quality management. Both simulations and real-world experiments support the effectiveness of this hybrid method, suggesting a strong foundation for intelligent power quality solutions in future smart grid applications. The research concludes that although deep learning models offer superior accuracy and predictive power for complex power quality scenarios, practical deployment requires careful balancing of computational demands and addressing class distribution challenges.
  • Toward 6G: An Overview of the Next Generation of Intelligent Network Connectivity

    Prasad Tera S., Chinthaginjala R., Pau G., Hoon Kim T.

    Review, IEEE Access, 2025, DOI Link

    View abstract ⏷

    The development of 6G networks represents a groundbreaking leap in mobile communication, targeting the creation of an Intelligent Network of Everything that seamlessly integrates advanced technologies such as Artificial Intelligence (AI), Machine Learning (ML), and the Internet of Everything (IoE). This next-generation network is projected to begin standardization in 2025, with commercial deployment anticipated by 2030. Building on the foundation of its predecessors, 6G aims to deliver ultra-reliable, low-latency, and high-speed communication essential for applications like autonomous systems, immersive virtual environments, and smart cities. This article provides a comprehensive overview of 6G, articulating its vision and identifying the core technologies that will enable its transformative capabilities. The key contributions of this work include a detailed exploration of prospective 6G applications and use cases, such as autonomous systems and integrated communication-sensing scenarios. Additionally, it identifies major challenges - such as advanced coding schemes, energy management, and security - and presents a roadmap for future research in these critical areas. The study also reviews potential coding and modulation techniques, such as non-binary codes and lattice codes, assessing their suitability for 6G's stringent performance requirements. Security and privacy considerations are also covered, proposing a robust architecture across all network layers to address emerging threats. Furthermore, the article compiles a literature review on 6G visions and surveys, providing valuable insights into the current state of research, highlighting gaps, and guiding future studies. Through the exploration of spectrum advancements, antenna technologies, network intelligence, and AI/ML integration, this work establishes a clear vision for how 6G can reshape global communication infrastructure and drive innovation in a hyper-connected world.
  • Exploring the Mathematical Foundations of Generative AI Models: VAEs, GANs, Transformers, and DMs

    Prasad Tera S., Ravikumar C.V., Natha P., Pau G.

    Article, IEEE Access, 2025, DOI Link

    View abstract ⏷

    Generative Artificial Intelligence (GAI) has rapidly advanced, revolutionizing content creation across diverse domains, including text, image, audio, and video synthesis. Generative models, including Transformers, Variational Autoencoders (VAEs), Diffusion Models, and Generative Adversarial Networks (GANs) are built on strong mathematical principles that support their ability to learn intricate data patterns and produce high-quality synthetic outputs. This article presents a comprehensive exploration of the mathematical principles that underpin these models, including key concepts such as probabilistic inference, minimax optimization, self-attention mechanisms, and diffusion processes. By focusing on foundational mathematical constructs—such as Evidence Lower Bound (ELBO) optimization in VAEs, adversarial training objectives in GANs, scaled dot-product attention in Transformers, and iterative denoising in Diffusion Models—this work elucidates how each model leverages these principles to achieve generative capabilities. The study highlights the application of these mathematical foundations across varied generative tasks and examines their impact on real-world challenges in sectors like healthcare, media, and scientific research. Additionally, this article addresses the growing need for ongoing mathematical refinement and innovation in GAI to tackle emerging ethical, privacy, and security challenges. Through this examination, we aim to provide researchers, practitioners, and policymakers with a deep understanding of the mathematical basis for modern generative models, guiding future developments in GAI.
  • Improving CNN predictive accuracy in COVID-19 health analytics

    Kim T.-H., Srinivasulu A., Chinthaginjala R., Dhakshayani J., Zhao X., Obaidur Rab S., Tera S.P.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    The COVID-19 pandemic has underscored the critical necessity for robust and accurate predictive frameworks to bolster global healthcare infrastructures. This study presents a comprehensive examination of convolutional neural networks (CNNs) applied to the prediction of COVID-19-related health outcomes, with an emphasis on core challenges, methodological constraints, and potential remediation strategies. Our investigation targets two principal aims: the identification of COVID-19 infections through chest radiographic imaging, specifically X-rays, and the prognostication of disease severity by integrating clinical parameters and electronic health records. Utilizing a multidimensional dataset encompassing demographic, clinical, and radiological information, we evaluated the efficacy of CNN architectures in forecasting patient prognoses. The CNN model attained an accuracy of 97.2%, reflecting its capability while simultaneously revealing significant challenges, including limited and imbalanced data, as well as difficulties in model interpretability. Principal limitations identified comprise overfitting, data heterogeneity, and the imperative for model adaptability amid evolving SARS-CoV-2 variants. To mitigate these issues, we propose strategies such as data augmentation, transfer learning, ensemble modeling, and enhancements in explainability, which collectively demonstrated improvements in predictive performance and theoretical robustness. This work highlights the imperative for continuous model refinement and the integration of domain-specific expertise to elevate the reliability and applicability of CNN-based prognostic tools for COVID-19 healthcare analytics. Our empirical results indicate that the CNN achieved a precision of 96.8%, an F1-score of 97.2%, and an AUC-ROC of 0.987, underscoring its effectiveness in detecting and classifying COVID-19 cases. These insights provide valuable directions for researchers and clinicians, fostering data-driven approaches in the management and prediction of COVID-19 health outcomes.
  • Boosting skin cancer diagnosis accuracy with ensemble approach

    Natha P., Tera S.P., Chinthaginjala R., Rab S.O., Narasimhulu C.V., Kim T.H.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    Skin cancer is common and deadly, hence a correct diagnosis at an early age is essential. Effective therapy depends on precise classification of the several skin cancer forms, each with special traits. Because dermoscopy and other sophisticated imaging methods produce detailed lesion images, early detection has been enhanced. It’s still difficult to analyze the images to differentiate benign from malignant tumors, though. Better predictive modeling methods are needed since the diagnostic procedures used now frequently produce inaccurate and inconsistent results. In dermatology, Machine learning (ML) models are becoming essential for the automatic detection and classification of skin cancer lesions from image data. With the ensemble model, which mix several ML approaches to take use of their advantages and lessen their disadvantages, this work seeks to improve skin cancer predictions. We introduce a new method, the Max Voting method, for optimization of skin cancer classification. On the HAM10000 and ISIC 2018 datasets, we trained and assessed three distinct ML models: Random Forest (RF), Multi-layer Perceptron Neural Network (MLPN), and Support Vector Machine (SVM). Overall performance was increased by the combined predictions made with the Max Voting technique. Moreover, feature vectors that were optimally produced from image data by a Genetic Algorithm (GA) were given to the ML models. We demonstrate that the Max Voting method greatly improves predictive performance, reaching an accuracy of 94.70% and producing the best results for F1-measure, recall, and precision. The most dependable and robust approach turned out to be Max Voting, which combines the benefits of numerous pre-trained ML models to provide a new and efficient method for classifying skin cancer lesions.
  • Deep learning approach for automated hMPV classification

    Tera S.P., Chinthaginjala R., Shahzadi I., Natha P., Rab S.O.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    Human metapneumovirus (hMPV) is a significant cause of respiratory illness, particularly in children, elderly individuals, and immunocompromised patients. Despite its clinical relevance, hMPV poses diagnostic challenges due to its symptom similarity with other respiratory illnesses, such as influenza and respiratory syncytial virus (RSV), and the lack of specialized detection systems. Traditional diagnostic methods are often inadequate for providing rapid and accurate results, particularly in low-resource settings. This study proposes a novel deep learning framework, referred to as hMPV-Net, which leverages Convolutional Neural Networks (CNNs) to facilitate the precise detection and classification of hMPV infections. The CNN model is designed to perform binary classification by differentiating between hMPV-positive and hMPV-negative cases. To address the lack of real-world patient data, simulated image datasets were used for model training and evaluation, allowing the model to generalize to various clinical scenarios. A key challenge in developing this model is the imbalance within the dataset, where hMPV-positive cases are often underrepresented. To mitigate this, the framework incorporates advanced techniques such as data augmentation, weighted loss functions, and dropout regularization, which help to balance the dataset, improve model robustness, and enhance classification accuracy. These techniques are crucial in addressing issues such as overfitting and generalization, which are common when working with limited datasets in medical imaging tasks. The dataset used for model training and testing consists of 10,000 samples, with an equal distribution of hMPV-positive and hMPV-negative cases. Experimental results demonstrate that the hMPV-Net model achieves a high test accuracy of 91.8%, along with impressive test precision, recall, and F1-score values around 92%. These metrics indicate that the model performs exceptionally well in classifying both hMPV-positive and hMPV-negative cases. Furthermore, the model exhibits superior computational efficiency, requiring only 3.2 GFLOPs, which is significantly lower than other state-of-the-art models such as ResNet-50 and VGG-16. This reduction in computational cost makes the model suitable for deployment in resource-constrained healthcare environments, where computing power and infrastructure may be limited.
  • COVID-19 health data prediction: a critical evaluation of CNN-based approaches

    Kim T.H., Chinthaginjala R., Srinivasulu A., Tera S.P., Rab S.O.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    The COVID-19 pandemic has significantly accelerated the demand for accurate and efficient prediction models to support effective disease management, containment strategies, and informed decision-making. Predictive models capable of analyzing complex health data are essential for monitoring disease trends, evaluating risk factors, and optimizing resource allocation during the pandemic. Among various machine learning approaches, convolutional neural networks (CNNs) have emerged as powerful tools due to their ability to process large volumes of high-dimensional health data, such as medical images, time-series data, and patient demographics, with impressive precision. This research seeks to systematically examine the challenges and limitations inherent in utilizing CNNs for COVID-19 health data prediction, offering a comprehensive perspective grounded in data science research. Key areas of investigation include issues related to data quality and availability, such as incomplete, noisy, and imbalanced datasets, which often hinder the training of robust models. Additionally, architectural constraints of CNNs, including their sensitivity to hyperparameter tuning and reliance on substantial computational resources, are explored as critical bottlenecks that impact scalability and efficiency. A significant focus is placed on generalization challenges, where models trained on specific datasets struggle to adapt to unseen data from diverse populations or clinical settings, limiting their applicability in real-world scenarios. The study further highlights a reported accuracy of 63%, underscoring the need for improved methodologies to enhance model performance and reliability. By addressing these challenges, this research aims to provide actionable insights and practical recommendations to optimize the use of CNNs for COVID-19 health data prediction. In particular, the study emphasizes the importance of incorporating advanced strategies such as transfer learning, data augmentation, and regularization techniques to overcome dataset limitations and enhance model robustness. The integration of multimodal approaches combining medical images with auxiliary data, such as patient demographics and laboratory results, is proposed to improve contextual understanding and diagnostic precision. Finally, the research underscores the necessity of interdisciplinary collaboration, leveraging domain expertise from data scientists, healthcare professionals, and epidemiologists to develop holistic solutions for tackling the complexities of COVID-19 prediction. By shedding light on the limitations and potential of CNNs in this domain, this study aims to guide researchers and practitioners in making informed decisions about model design, implementation, and optimization. Ultimately, it contributes to advancing AI-driven diagnostics and predictive modeling for COVID-19 and other public health crises, fostering the development of scalable and reliable tools for better healthcare outcomes.
  • Deep learning assisted LDPC decoding for 5G IoT networks in fading environments

    Prasad S., Chinthaginjala R., Al-Turjman F., Ahmad S.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    With the deployment of 5G networks, the Internet of Things (IoT) has experienced a transformative boost, enabling higher data rates, reduced latency, and the connection of millions of devices across applications like smart cities, healthcare, and industrial automation. However, in real-world scenarios, the performance of Low-Density Parity-Check (LDPC) codes, the preferred channel coding scheme in 5G, is severely affected by noise and fading environments, particularly colored noise, which distorts signals over certain frequency bands. Colored noise introduces correlation in the interference, unlike white noise, thereby posing a challenge in decoding, especially in fading channels such as Rayleigh, Rician, and Nakagami-m. In this work, we propose a novel approach that combines the Iterative Offset Min-Sum (OMS) algorithm with a Convolutional Neural Network (CNN) to enhance LDPC decoding efficiency in 5G-enabled IoT networks. Our proposed OMS-CNN hybrid architecture addresses the limitations imposed by colored noise in fading channels by employing deep learning techniques for accurate noise estimation and mitigation. Furthermore, the OMS algorithm mitigates the overestimation of noise correction, refining the output in iterative decoding steps. Through comprehensive simulations, the OMS-CNN decoder demonstrates substantial improvements over traditional decoding approaches. Specifically, it achieves a performance enhancement of 2.7 dB at a bit error rate (BER) of across a range of fading channels. The study examines the decoder’s performance in environments characterized by Rayleigh, Rician, and Nakagami-m fading models, highlighting the robustness of the proposed solution under different channel conditions. Additionally, this research explores the influence of parameters such as the correlation coefficient of the noise, the scaling factor in the cost function, and the number of iterations between the CNN and OMS decoding steps.
  • Correction: Deep learning assisted LDPC decoding for 5G IoT networks in fading environments (Scientific Reports, (2025), 15, 1, (37469), 10.1038/s41598-025-21382-y)

    Tera S.P., Chinthaginjala R., Al-Turjman F., Ahmad S.

    Erratum, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    Correction to: Scientific Reportshttps://doi.org/10.1038/s41598-025-21382-y, published online 27 October 2025 The original version of this Article contained an error in the spelling of the author Sivarama Prasad Tera which was incorrectly given as Sivarama Prasad. In addition, Sivarama Prasad Tera was incorrectly affiliated with ‘Department of Electronics and Electrical Engineering, Indian Institute of Technology, Guwahati, Assam 781039, India’. The correct affiliation is ‘School of Electrical Engineering, Kore University of Enna, Enna, Italy’. The original Article has been corrected.
  • Deep Learning Approach for Efficient 5G LDPC Decoding in IoT

    Tera S.P., Chinthaginjala R.V., Natha P., Ahmad S., Pau G.

    Article, IEEE Access, 2024, DOI Link

    View abstract ⏷

    The tremendous progress of 5G technology has transformed the landscape of the Internet of Things (IoT), allowing for fast data speeds, low delay, and widespread connection that is crucial for a variety of applications, including smart cities and industrial automation. In the context of 5G enabled IoT networks, colored noise introduces varying levels of interference across different frequency bands, which can significantly degrade the performance of 5G LDPC decoding. This paper presents a novel Deep learning approach for 5G channel LDPC code decoding tailored for next-generation IoT applications. The proposed method integrates an Iterative Normalized Min-Sum (NMS) algorithm with a Convolutional Neural Network (CNN) to enhance the performance of LDPC decoding in the presence of colored noise, a common interference in real-world communication channels. Through extensive simulations and analysis, our approach demonstrates a significant performance improvement, achieving a 3.8 dB enhancement at a Bit error rate of 10-6. This is achieved by accurately estimating and mitigating channel noise, thereby ensuring reliable data transmission for critical IoT applications. The findings indicate that our approach to decoding technique not only enhances error correction capabilities but also adapts to varying channel conditions, optimizing IoT network performance and efficiency. This research contributes a robust solution to the challenges posed by colored noise in 5G-enabled IoT networks, promoting the deployment of more reliable and efficient IoT systems.
  • CNN-Based Approach for Enhancing 5G LDPC Code Decoding Performance

    Tera S.P., Chinthaginjala R., Natha P., Pau G., Dhanamjayulu C., Mohammad F.

    Article, IEEE Access, 2024, DOI Link

    View abstract ⏷

    This paper presents the novel Stochastic decoding-convolutional neural network (SD-CNN) structure, with the goal of enhancing 5G LDPC code's decoding efficiency in the presence of correlated noise of the channel. Applying the stochastic approach acts as an alternate technique to fixed-point LDPC decoding to enhance the decoder's hardware efficiency. In order to improve the efficacy of the decoder, we adopted deep learning method such as Convolutional neural network (CNN). CNNs can be employed for denoising purposes in communication systems, where signals may be compromised by diverse forms of noise while being transmitted, with the aim of enhancing signal quality and dependability. The SD-CNN architecture combines a trained CNN with a stochastic decoder of 5G LDPC codes, thereby utilizing the CNN's capability to accurately estimate channel noise and, consequently, enhance the error correction capabilities of the decoder. The generated output of the trained CNN is then fed back into the stochastic decoder, creating an iterative process between the SD and CNN that ultimately leads to superior decoding performance. For 5G LDPC code word length N = 3808 , with a base code rate R = 1/3, the suggested SD-CNN architecture achieves a BER of 10-6 at 0.6 dB of SNR per bit in the strong correlation of channel noise condition, in comparison to SD, which achieves a BER of 10-6 at 3.5 dB of SNR per bit. The results demonstrate that there is a 2.9 dB improvement.
  • A Flexible FPGA-Based Stochastic Decoder for 5G LDPC Codes

    Tera S.P., Alantattil R., Paily R.

    Article, Electronics (Switzerland), 2023, DOI Link

    View abstract ⏷

    Iterative stochastic decoding is an alternative to standard fixed-point decoding of low-density parity check (LDPC) codes that can be used to minimize inter-node routing. A flexible field-programmable gate array (FPGA)-based stochastic decoding (SD) hardware architecture is presented in this paper. The architecture is designed to decode different code rates of LDPC codes that comply with the fifth-generation (5G) New Radio (NR) standard. This decoder’s runtime flexibility is desirable as it switches to a better-performing code rate automatically based on the channel conditions without the extra time needed to reprogram the FPGA. An offline design method is implemented to generate the hardware description language (HDL) code description of the decoder for the required code rate set, which is further synthesized and integrated into a Xilinx Kintex-7-series FPGA board to determine the hardware resource utilisation and processing throughput. Synopsys design tools were employed during both the simulation and synthesis stages in combination with TSMC 65 nm CMOS standard cell technology to facilitate comparative analysis. Compared with state-of-the-art designs, the proposed architecture reduces hardware utilization by up to 26% and increases energy efficiency by 52%.
  • Optimal implementation of UART-SPI Interface in SoC

    Praveen Blessington T., Bhanu Murthy B., Ganesh G.V., Prasad T.S.R.

    Conference paper, 2012 International Conference on Devices, Circuits and Systems, ICDCS 2012, 2012, DOI Link

    View abstract ⏷

    This paper details the design and implementation of SoC's UART-SPI Interface. The UART-SPI interface provides usage for the universal asynchronous receiver/transmitter (UART) to serial peripheral interface (SPI). This interface can be used to communicate to SPI slave devices from a PC with UART port. The interface consists of three blocks: the UART interface, the UART-to-SPI interfacing block and the SPI Master interface. © 2012 IEEE.

Patents

Projects

Scholars

Interests

  • Digital VLSI
  • Machine Learning

Thought Leaderships

There are no Thought Leaderships associated with this faculty.

Top Achievements

Research Area

No research areas found for this faculty.

Computer Science and Engineering is a fast-evolving discipline and this is an exciting time to become a Computer Scientist!

Computer Science and Engineering is a fast-evolving discipline and this is an exciting time to become a Computer Scientist!

Recent Updates

No recent updates found.

Education
2001
B.Tech
JNTU KAKINADA
India
2004
M.Tech
MNNIT Allahabad
India
2025
Ph.D.
IIT Guwahati
India
Experience
  • Assistant Professor, ECE, KLUniversity, Andhra Pradesh
Research Interests
  • 6G 5G Channel Decoders, FPGA and ASIC Implementations
  • Machine Learning, Generative AI
Awards & Fellowships
Memberships
Publications
  • A Scalable Ensemble Learning Framework for Accurate and Equitable Global Life Expectancy Prediction

    Chinthaginjala R., Tera S.P., El-Shafai W., Azar A.T., Kamal N.A.

    Conference paper, 2026 International Conference on Control, Automation and Diagnosis, ICCAD 2026, 2026, DOI Link

    View abstract ⏷

    Life expectancy prediction using machine learning can support public health planning and policy making, yet practical guidance on selecting among ensemble methods for population-level modeling remains limited. This study evaluates four ensemble regressors, Random Forest, XGBoost, LightGBM, and Gradient Boosting, for global life expectancy prediction under a unified experimental protocol. We use a dataset of 22,050 observations from 195 countries with 149 health and socioeconomic indicators. Models are tuned via extensive hyperparameter search with stratified cross-validation, and computational efficiency is assessed alongside predictive accuracy. Performance is reported using the coefficient of determination (R2), root mean squared error (RMSE), and mean absolute error (MAE), both overall and stratified by country income group. XGBoost achieves the highest test accuracy (R2 = 0.9943, RMSE = 0.7386 years, MAE = 0.4448 years), outperforming Gradient Boosting (R2 = 0.9908), LightGBM (R2 = 0.9860), and Random Forest (R2 = 0.9856). Performance remains strong across income strata, although lower accuracy in low- and lower-middle-income settings suggests heterogeneous predictability across development contexts. Overall, XGBoost provides the best accuracy-efficiency trade-off under the adopted country-year split, while country-held-out and temporal validation are required before claiming full out-of-country generalization.
  • An Interpretable and Resource-Efficient Machine Learning Framework for Diabetes Detection Under Class Imbalance

    Chinthaginjala R., Tera S.P., El-Shafai W., Azar A.T., Kamal N.A.

    Conference paper, 2026 International Conference on Control, Automation and Diagnosis, ICCAD 2026, 2026, DOI Link

    View abstract ⏷

    Diabetes mellitus is a major global health challenge, motivating reliable early-detection tools for timely intervention. This paper provides a comparative evaluation of traditional machine learning models, Logistic Regression, Support Vector Machines (SVM), Random Forest, and K-Nearest Neighbors (KNN), for diabetes prediction on the DiaBD dataset (5,288 patient records from Bangladesh). To address the pronounced class imbalance (6.5% diabetic vs. 93.5% non-diabetic), we apply the Synthetic Minority Over-sampling Technique (SMOTE) to the training data and assess performance using accuracy, precision, recall, F1-score, and ROC-AUC. Experimental results show that Random Forest yields the best overall performance after SMOTE, achieving 93.67% accuracy and 0.8798 ROC-AUC, outperforming the remaining traditional baselines. Feature-importance analysis further indicates that hypertension, glucose-related measures, and blood pressure are the most informative predictors. These findings support the practical use of traditional, interpretable machine learning models for diabetes risk assessment in resource-constrained healthcare settings.
  • A multi-stage stacking framework for accurate and interpretable life expectancy modeling

    Chinthaginjala R., Tera S.P., Natha P., Srinivasulu A., Al-Turjman F., Mohammad F.

    Article, PLOS One, 2026, DOI Link

    View abstract ⏷

    Accurate life-expectancy estimation is critical for evidence-based health policy, monitoring Sustainable Development Goal 3 (SDG 3), and guiding global resource allocation. Existing machine-learning approaches typically provide point predictions with limited interpretability and uncertainty quantification. To address these limitations, we propose NEXUS-LE (Neuro-Symbolic Explainable Unified Stacking for Life Expectancy), a unified ensemble framework that integrates predictive accuracy, calibrated uncertainty, and policy-level explainability. The model is trained on a global dataset comprising 22,050 country-year observations across 193 countries (2000-2021) and 150 World Health Organization indicators. The framework combines leave-one-out encoding, principal component analysis, and K-Means-based manifold features with SHAP-guided polynomial expansion and a three-level stacking architecture, followed by a LightGBM residual correction and split-conformal calibration. On a held-out test set (n = 3,308), the model achieves R2 = 0.9878, RMSE = 1.0665 years, MAE = 0.6185 years, and MAPE = 0.9239%. Conformal prediction attains 95.04% empirical coverage at the 95% nominal level with a 90% interval width of 3.32 years. Interpretability analysis shows that demographic and structural factors contribute 96.3% of total attribution, with consistent non-linear effects across policy domains. The proposed framework provides a reliable and interpretable solution for life-expectancy prediction in global health applications.
  • Advancing quantum machine learning from conceptual design to practical use

    Tera S.P., Chinthaginjala R., Zhao X., Hamdi M.

    Review, Expert Systems with Applications, 2026, DOI Link

    View abstract ⏷

    This study presents an integrated assessment of quantum machine learning (QML) that combines quantum-computing foundations, algorithmic design, hardware constraints, and empirical evidence into a single, coherent framework. Drawing on a PRISMA-compliant systematic review of 142 peer-reviewed articles published between 2016 and 2025, the study analyzes how QML methods are actually performing on current noisy intermediate-scale quantum (NISQ) devices and against well-tuned classical baselines. A seven-dimensional taxonomy is introduced that organizes the QML design space along data encoding, model paradigms (QSVM, QPCA, QNN, VQC, QBM), training and optimization, hardware platforms, application domains, evaluation protocols, and technology-readiness levels, with method-selection guidelines for each axis. For the five core QML model families, the survey provides end-to-end workflows and comparative evidence tables reporting datasets, hyperparameters, resource usage (qubits, circuit depth, shots, wall-clock time), performance metrics with uncertainty, and explicit advantage classifications. The results show that, under fair comparisons with optimized classical methods and full resource accounting, QML currently yields parity at best—and often classical superiority—for supervised learning on classical data, while the most credible near-term benefits arise in quantum-native domains such as quantum chemistry and many-body physics. The study further proposes an eight-criterion quantum-advantage evaluation framework and a challenge taxonomy that quantify key obstacles—including decoherence, barren plateaus, data-loading overhead, classical competition, and scalability limits—and outline realistic pathways toward future fault-tolerant, quantum-native QML applications.
  • Hybrid AI and semiconductor approaches for power quality improvement

    Chinthaginjala R., Srinivasulu A., Agrawal A., Kim T.H., Tera S.P., Ahmad S.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    This research presents a novel approach to improving electric power quality using semiconductor devices by integrating Machine Learning (ML), Deep Learning (DL), and advanced control strategies. The research addresses key power quality challenges - including voltage sags, swells, harmonics, and transient disturbances - through a data-driven framework that combines traditional control techniques with adaptive learning models. A variety of algorithms, including Support Vector Machines (SVM), Random Forests, Neural Networks, Convolutional Neural Networks (CNN), and Long Short-Term Memory (LSTM) networks, were tested using real-time data. The results showed notable differences in performance, with deep learning models, especially LSTM, proving to be more accurate and dependable in identifying and forecasting power quality issues. In contrast, traditional ML models like SVM and Random Forest had difficulties with class imbalance, resulting in lower precision and recall. DL models, however, managed these challenges effectively, with CNN achieving a precision of 91.8% and LSTM attaining perfect accuracy (100%) and a recall of 94.5%. The study also highlighted the complications of handling imbalanced datasets, as indicated by classification warnings, emphasizing the importance of improved preprocessing and model adjustments for reliable predictions. The execution times varied significantly, with traditional control systems being faster but less capable in identifying complex patterns compared to the computationally intensive DL models. These findings highlight the promise of hybrid systems that integrate both traditional and data-driven control strategies to achieve adaptive and dependable power quality management. Both simulations and real-world experiments support the effectiveness of this hybrid method, suggesting a strong foundation for intelligent power quality solutions in future smart grid applications. The research concludes that although deep learning models offer superior accuracy and predictive power for complex power quality scenarios, practical deployment requires careful balancing of computational demands and addressing class distribution challenges.
  • Toward 6G: An Overview of the Next Generation of Intelligent Network Connectivity

    Prasad Tera S., Chinthaginjala R., Pau G., Hoon Kim T.

    Review, IEEE Access, 2025, DOI Link

    View abstract ⏷

    The development of 6G networks represents a groundbreaking leap in mobile communication, targeting the creation of an Intelligent Network of Everything that seamlessly integrates advanced technologies such as Artificial Intelligence (AI), Machine Learning (ML), and the Internet of Everything (IoE). This next-generation network is projected to begin standardization in 2025, with commercial deployment anticipated by 2030. Building on the foundation of its predecessors, 6G aims to deliver ultra-reliable, low-latency, and high-speed communication essential for applications like autonomous systems, immersive virtual environments, and smart cities. This article provides a comprehensive overview of 6G, articulating its vision and identifying the core technologies that will enable its transformative capabilities. The key contributions of this work include a detailed exploration of prospective 6G applications and use cases, such as autonomous systems and integrated communication-sensing scenarios. Additionally, it identifies major challenges - such as advanced coding schemes, energy management, and security - and presents a roadmap for future research in these critical areas. The study also reviews potential coding and modulation techniques, such as non-binary codes and lattice codes, assessing their suitability for 6G's stringent performance requirements. Security and privacy considerations are also covered, proposing a robust architecture across all network layers to address emerging threats. Furthermore, the article compiles a literature review on 6G visions and surveys, providing valuable insights into the current state of research, highlighting gaps, and guiding future studies. Through the exploration of spectrum advancements, antenna technologies, network intelligence, and AI/ML integration, this work establishes a clear vision for how 6G can reshape global communication infrastructure and drive innovation in a hyper-connected world.
  • Exploring the Mathematical Foundations of Generative AI Models: VAEs, GANs, Transformers, and DMs

    Prasad Tera S., Ravikumar C.V., Natha P., Pau G.

    Article, IEEE Access, 2025, DOI Link

    View abstract ⏷

    Generative Artificial Intelligence (GAI) has rapidly advanced, revolutionizing content creation across diverse domains, including text, image, audio, and video synthesis. Generative models, including Transformers, Variational Autoencoders (VAEs), Diffusion Models, and Generative Adversarial Networks (GANs) are built on strong mathematical principles that support their ability to learn intricate data patterns and produce high-quality synthetic outputs. This article presents a comprehensive exploration of the mathematical principles that underpin these models, including key concepts such as probabilistic inference, minimax optimization, self-attention mechanisms, and diffusion processes. By focusing on foundational mathematical constructs—such as Evidence Lower Bound (ELBO) optimization in VAEs, adversarial training objectives in GANs, scaled dot-product attention in Transformers, and iterative denoising in Diffusion Models—this work elucidates how each model leverages these principles to achieve generative capabilities. The study highlights the application of these mathematical foundations across varied generative tasks and examines their impact on real-world challenges in sectors like healthcare, media, and scientific research. Additionally, this article addresses the growing need for ongoing mathematical refinement and innovation in GAI to tackle emerging ethical, privacy, and security challenges. Through this examination, we aim to provide researchers, practitioners, and policymakers with a deep understanding of the mathematical basis for modern generative models, guiding future developments in GAI.
  • Improving CNN predictive accuracy in COVID-19 health analytics

    Kim T.-H., Srinivasulu A., Chinthaginjala R., Dhakshayani J., Zhao X., Obaidur Rab S., Tera S.P.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    The COVID-19 pandemic has underscored the critical necessity for robust and accurate predictive frameworks to bolster global healthcare infrastructures. This study presents a comprehensive examination of convolutional neural networks (CNNs) applied to the prediction of COVID-19-related health outcomes, with an emphasis on core challenges, methodological constraints, and potential remediation strategies. Our investigation targets two principal aims: the identification of COVID-19 infections through chest radiographic imaging, specifically X-rays, and the prognostication of disease severity by integrating clinical parameters and electronic health records. Utilizing a multidimensional dataset encompassing demographic, clinical, and radiological information, we evaluated the efficacy of CNN architectures in forecasting patient prognoses. The CNN model attained an accuracy of 97.2%, reflecting its capability while simultaneously revealing significant challenges, including limited and imbalanced data, as well as difficulties in model interpretability. Principal limitations identified comprise overfitting, data heterogeneity, and the imperative for model adaptability amid evolving SARS-CoV-2 variants. To mitigate these issues, we propose strategies such as data augmentation, transfer learning, ensemble modeling, and enhancements in explainability, which collectively demonstrated improvements in predictive performance and theoretical robustness. This work highlights the imperative for continuous model refinement and the integration of domain-specific expertise to elevate the reliability and applicability of CNN-based prognostic tools for COVID-19 healthcare analytics. Our empirical results indicate that the CNN achieved a precision of 96.8%, an F1-score of 97.2%, and an AUC-ROC of 0.987, underscoring its effectiveness in detecting and classifying COVID-19 cases. These insights provide valuable directions for researchers and clinicians, fostering data-driven approaches in the management and prediction of COVID-19 health outcomes.
  • Boosting skin cancer diagnosis accuracy with ensemble approach

    Natha P., Tera S.P., Chinthaginjala R., Rab S.O., Narasimhulu C.V., Kim T.H.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    Skin cancer is common and deadly, hence a correct diagnosis at an early age is essential. Effective therapy depends on precise classification of the several skin cancer forms, each with special traits. Because dermoscopy and other sophisticated imaging methods produce detailed lesion images, early detection has been enhanced. It’s still difficult to analyze the images to differentiate benign from malignant tumors, though. Better predictive modeling methods are needed since the diagnostic procedures used now frequently produce inaccurate and inconsistent results. In dermatology, Machine learning (ML) models are becoming essential for the automatic detection and classification of skin cancer lesions from image data. With the ensemble model, which mix several ML approaches to take use of their advantages and lessen their disadvantages, this work seeks to improve skin cancer predictions. We introduce a new method, the Max Voting method, for optimization of skin cancer classification. On the HAM10000 and ISIC 2018 datasets, we trained and assessed three distinct ML models: Random Forest (RF), Multi-layer Perceptron Neural Network (MLPN), and Support Vector Machine (SVM). Overall performance was increased by the combined predictions made with the Max Voting technique. Moreover, feature vectors that were optimally produced from image data by a Genetic Algorithm (GA) were given to the ML models. We demonstrate that the Max Voting method greatly improves predictive performance, reaching an accuracy of 94.70% and producing the best results for F1-measure, recall, and precision. The most dependable and robust approach turned out to be Max Voting, which combines the benefits of numerous pre-trained ML models to provide a new and efficient method for classifying skin cancer lesions.
  • Deep learning approach for automated hMPV classification

    Tera S.P., Chinthaginjala R., Shahzadi I., Natha P., Rab S.O.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    Human metapneumovirus (hMPV) is a significant cause of respiratory illness, particularly in children, elderly individuals, and immunocompromised patients. Despite its clinical relevance, hMPV poses diagnostic challenges due to its symptom similarity with other respiratory illnesses, such as influenza and respiratory syncytial virus (RSV), and the lack of specialized detection systems. Traditional diagnostic methods are often inadequate for providing rapid and accurate results, particularly in low-resource settings. This study proposes a novel deep learning framework, referred to as hMPV-Net, which leverages Convolutional Neural Networks (CNNs) to facilitate the precise detection and classification of hMPV infections. The CNN model is designed to perform binary classification by differentiating between hMPV-positive and hMPV-negative cases. To address the lack of real-world patient data, simulated image datasets were used for model training and evaluation, allowing the model to generalize to various clinical scenarios. A key challenge in developing this model is the imbalance within the dataset, where hMPV-positive cases are often underrepresented. To mitigate this, the framework incorporates advanced techniques such as data augmentation, weighted loss functions, and dropout regularization, which help to balance the dataset, improve model robustness, and enhance classification accuracy. These techniques are crucial in addressing issues such as overfitting and generalization, which are common when working with limited datasets in medical imaging tasks. The dataset used for model training and testing consists of 10,000 samples, with an equal distribution of hMPV-positive and hMPV-negative cases. Experimental results demonstrate that the hMPV-Net model achieves a high test accuracy of 91.8%, along with impressive test precision, recall, and F1-score values around 92%. These metrics indicate that the model performs exceptionally well in classifying both hMPV-positive and hMPV-negative cases. Furthermore, the model exhibits superior computational efficiency, requiring only 3.2 GFLOPs, which is significantly lower than other state-of-the-art models such as ResNet-50 and VGG-16. This reduction in computational cost makes the model suitable for deployment in resource-constrained healthcare environments, where computing power and infrastructure may be limited.
  • COVID-19 health data prediction: a critical evaluation of CNN-based approaches

    Kim T.H., Chinthaginjala R., Srinivasulu A., Tera S.P., Rab S.O.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    The COVID-19 pandemic has significantly accelerated the demand for accurate and efficient prediction models to support effective disease management, containment strategies, and informed decision-making. Predictive models capable of analyzing complex health data are essential for monitoring disease trends, evaluating risk factors, and optimizing resource allocation during the pandemic. Among various machine learning approaches, convolutional neural networks (CNNs) have emerged as powerful tools due to their ability to process large volumes of high-dimensional health data, such as medical images, time-series data, and patient demographics, with impressive precision. This research seeks to systematically examine the challenges and limitations inherent in utilizing CNNs for COVID-19 health data prediction, offering a comprehensive perspective grounded in data science research. Key areas of investigation include issues related to data quality and availability, such as incomplete, noisy, and imbalanced datasets, which often hinder the training of robust models. Additionally, architectural constraints of CNNs, including their sensitivity to hyperparameter tuning and reliance on substantial computational resources, are explored as critical bottlenecks that impact scalability and efficiency. A significant focus is placed on generalization challenges, where models trained on specific datasets struggle to adapt to unseen data from diverse populations or clinical settings, limiting their applicability in real-world scenarios. The study further highlights a reported accuracy of 63%, underscoring the need for improved methodologies to enhance model performance and reliability. By addressing these challenges, this research aims to provide actionable insights and practical recommendations to optimize the use of CNNs for COVID-19 health data prediction. In particular, the study emphasizes the importance of incorporating advanced strategies such as transfer learning, data augmentation, and regularization techniques to overcome dataset limitations and enhance model robustness. The integration of multimodal approaches combining medical images with auxiliary data, such as patient demographics and laboratory results, is proposed to improve contextual understanding and diagnostic precision. Finally, the research underscores the necessity of interdisciplinary collaboration, leveraging domain expertise from data scientists, healthcare professionals, and epidemiologists to develop holistic solutions for tackling the complexities of COVID-19 prediction. By shedding light on the limitations and potential of CNNs in this domain, this study aims to guide researchers and practitioners in making informed decisions about model design, implementation, and optimization. Ultimately, it contributes to advancing AI-driven diagnostics and predictive modeling for COVID-19 and other public health crises, fostering the development of scalable and reliable tools for better healthcare outcomes.
  • Deep learning assisted LDPC decoding for 5G IoT networks in fading environments

    Prasad S., Chinthaginjala R., Al-Turjman F., Ahmad S.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    With the deployment of 5G networks, the Internet of Things (IoT) has experienced a transformative boost, enabling higher data rates, reduced latency, and the connection of millions of devices across applications like smart cities, healthcare, and industrial automation. However, in real-world scenarios, the performance of Low-Density Parity-Check (LDPC) codes, the preferred channel coding scheme in 5G, is severely affected by noise and fading environments, particularly colored noise, which distorts signals over certain frequency bands. Colored noise introduces correlation in the interference, unlike white noise, thereby posing a challenge in decoding, especially in fading channels such as Rayleigh, Rician, and Nakagami-m. In this work, we propose a novel approach that combines the Iterative Offset Min-Sum (OMS) algorithm with a Convolutional Neural Network (CNN) to enhance LDPC decoding efficiency in 5G-enabled IoT networks. Our proposed OMS-CNN hybrid architecture addresses the limitations imposed by colored noise in fading channels by employing deep learning techniques for accurate noise estimation and mitigation. Furthermore, the OMS algorithm mitigates the overestimation of noise correction, refining the output in iterative decoding steps. Through comprehensive simulations, the OMS-CNN decoder demonstrates substantial improvements over traditional decoding approaches. Specifically, it achieves a performance enhancement of 2.7 dB at a bit error rate (BER) of across a range of fading channels. The study examines the decoder’s performance in environments characterized by Rayleigh, Rician, and Nakagami-m fading models, highlighting the robustness of the proposed solution under different channel conditions. Additionally, this research explores the influence of parameters such as the correlation coefficient of the noise, the scaling factor in the cost function, and the number of iterations between the CNN and OMS decoding steps.
  • Correction: Deep learning assisted LDPC decoding for 5G IoT networks in fading environments (Scientific Reports, (2025), 15, 1, (37469), 10.1038/s41598-025-21382-y)

    Tera S.P., Chinthaginjala R., Al-Turjman F., Ahmad S.

    Erratum, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    Correction to: Scientific Reportshttps://doi.org/10.1038/s41598-025-21382-y, published online 27 October 2025 The original version of this Article contained an error in the spelling of the author Sivarama Prasad Tera which was incorrectly given as Sivarama Prasad. In addition, Sivarama Prasad Tera was incorrectly affiliated with ‘Department of Electronics and Electrical Engineering, Indian Institute of Technology, Guwahati, Assam 781039, India’. The correct affiliation is ‘School of Electrical Engineering, Kore University of Enna, Enna, Italy’. The original Article has been corrected.
  • Deep Learning Approach for Efficient 5G LDPC Decoding in IoT

    Tera S.P., Chinthaginjala R.V., Natha P., Ahmad S., Pau G.

    Article, IEEE Access, 2024, DOI Link

    View abstract ⏷

    The tremendous progress of 5G technology has transformed the landscape of the Internet of Things (IoT), allowing for fast data speeds, low delay, and widespread connection that is crucial for a variety of applications, including smart cities and industrial automation. In the context of 5G enabled IoT networks, colored noise introduces varying levels of interference across different frequency bands, which can significantly degrade the performance of 5G LDPC decoding. This paper presents a novel Deep learning approach for 5G channel LDPC code decoding tailored for next-generation IoT applications. The proposed method integrates an Iterative Normalized Min-Sum (NMS) algorithm with a Convolutional Neural Network (CNN) to enhance the performance of LDPC decoding in the presence of colored noise, a common interference in real-world communication channels. Through extensive simulations and analysis, our approach demonstrates a significant performance improvement, achieving a 3.8 dB enhancement at a Bit error rate of 10-6. This is achieved by accurately estimating and mitigating channel noise, thereby ensuring reliable data transmission for critical IoT applications. The findings indicate that our approach to decoding technique not only enhances error correction capabilities but also adapts to varying channel conditions, optimizing IoT network performance and efficiency. This research contributes a robust solution to the challenges posed by colored noise in 5G-enabled IoT networks, promoting the deployment of more reliable and efficient IoT systems.
  • CNN-Based Approach for Enhancing 5G LDPC Code Decoding Performance

    Tera S.P., Chinthaginjala R., Natha P., Pau G., Dhanamjayulu C., Mohammad F.

    Article, IEEE Access, 2024, DOI Link

    View abstract ⏷

    This paper presents the novel Stochastic decoding-convolutional neural network (SD-CNN) structure, with the goal of enhancing 5G LDPC code's decoding efficiency in the presence of correlated noise of the channel. Applying the stochastic approach acts as an alternate technique to fixed-point LDPC decoding to enhance the decoder's hardware efficiency. In order to improve the efficacy of the decoder, we adopted deep learning method such as Convolutional neural network (CNN). CNNs can be employed for denoising purposes in communication systems, where signals may be compromised by diverse forms of noise while being transmitted, with the aim of enhancing signal quality and dependability. The SD-CNN architecture combines a trained CNN with a stochastic decoder of 5G LDPC codes, thereby utilizing the CNN's capability to accurately estimate channel noise and, consequently, enhance the error correction capabilities of the decoder. The generated output of the trained CNN is then fed back into the stochastic decoder, creating an iterative process between the SD and CNN that ultimately leads to superior decoding performance. For 5G LDPC code word length N = 3808 , with a base code rate R = 1/3, the suggested SD-CNN architecture achieves a BER of 10-6 at 0.6 dB of SNR per bit in the strong correlation of channel noise condition, in comparison to SD, which achieves a BER of 10-6 at 3.5 dB of SNR per bit. The results demonstrate that there is a 2.9 dB improvement.
  • A Flexible FPGA-Based Stochastic Decoder for 5G LDPC Codes

    Tera S.P., Alantattil R., Paily R.

    Article, Electronics (Switzerland), 2023, DOI Link

    View abstract ⏷

    Iterative stochastic decoding is an alternative to standard fixed-point decoding of low-density parity check (LDPC) codes that can be used to minimize inter-node routing. A flexible field-programmable gate array (FPGA)-based stochastic decoding (SD) hardware architecture is presented in this paper. The architecture is designed to decode different code rates of LDPC codes that comply with the fifth-generation (5G) New Radio (NR) standard. This decoder’s runtime flexibility is desirable as it switches to a better-performing code rate automatically based on the channel conditions without the extra time needed to reprogram the FPGA. An offline design method is implemented to generate the hardware description language (HDL) code description of the decoder for the required code rate set, which is further synthesized and integrated into a Xilinx Kintex-7-series FPGA board to determine the hardware resource utilisation and processing throughput. Synopsys design tools were employed during both the simulation and synthesis stages in combination with TSMC 65 nm CMOS standard cell technology to facilitate comparative analysis. Compared with state-of-the-art designs, the proposed architecture reduces hardware utilization by up to 26% and increases energy efficiency by 52%.
  • Optimal implementation of UART-SPI Interface in SoC

    Praveen Blessington T., Bhanu Murthy B., Ganesh G.V., Prasad T.S.R.

    Conference paper, 2012 International Conference on Devices, Circuits and Systems, ICDCS 2012, 2012, DOI Link

    View abstract ⏷

    This paper details the design and implementation of SoC's UART-SPI Interface. The UART-SPI interface provides usage for the universal asynchronous receiver/transmitter (UART) to serial peripheral interface (SPI). This interface can be used to communicate to SPI slave devices from a PC with UART port. The interface consists of three blocks: the UART interface, the UART-to-SPI interfacing block and the SPI Master interface. © 2012 IEEE.
Contact Details

sivaramaprasad.t@srmap.edu.in

Scholars
Interests

  • Digital VLSI
  • Machine Learning

Education
2001
B.Tech
JNTU KAKINADA
India
2004
M.Tech
MNNIT Allahabad
India
2025
Ph.D.
IIT Guwahati
India
Experience
  • Assistant Professor, ECE, KLUniversity, Andhra Pradesh
Research Interests
  • 6G 5G Channel Decoders, FPGA and ASIC Implementations
  • Machine Learning, Generative AI
Awards & Fellowships
Memberships
Publications
  • A Scalable Ensemble Learning Framework for Accurate and Equitable Global Life Expectancy Prediction

    Chinthaginjala R., Tera S.P., El-Shafai W., Azar A.T., Kamal N.A.

    Conference paper, 2026 International Conference on Control, Automation and Diagnosis, ICCAD 2026, 2026, DOI Link

    View abstract ⏷

    Life expectancy prediction using machine learning can support public health planning and policy making, yet practical guidance on selecting among ensemble methods for population-level modeling remains limited. This study evaluates four ensemble regressors, Random Forest, XGBoost, LightGBM, and Gradient Boosting, for global life expectancy prediction under a unified experimental protocol. We use a dataset of 22,050 observations from 195 countries with 149 health and socioeconomic indicators. Models are tuned via extensive hyperparameter search with stratified cross-validation, and computational efficiency is assessed alongside predictive accuracy. Performance is reported using the coefficient of determination (R2), root mean squared error (RMSE), and mean absolute error (MAE), both overall and stratified by country income group. XGBoost achieves the highest test accuracy (R2 = 0.9943, RMSE = 0.7386 years, MAE = 0.4448 years), outperforming Gradient Boosting (R2 = 0.9908), LightGBM (R2 = 0.9860), and Random Forest (R2 = 0.9856). Performance remains strong across income strata, although lower accuracy in low- and lower-middle-income settings suggests heterogeneous predictability across development contexts. Overall, XGBoost provides the best accuracy-efficiency trade-off under the adopted country-year split, while country-held-out and temporal validation are required before claiming full out-of-country generalization.
  • An Interpretable and Resource-Efficient Machine Learning Framework for Diabetes Detection Under Class Imbalance

    Chinthaginjala R., Tera S.P., El-Shafai W., Azar A.T., Kamal N.A.

    Conference paper, 2026 International Conference on Control, Automation and Diagnosis, ICCAD 2026, 2026, DOI Link

    View abstract ⏷

    Diabetes mellitus is a major global health challenge, motivating reliable early-detection tools for timely intervention. This paper provides a comparative evaluation of traditional machine learning models, Logistic Regression, Support Vector Machines (SVM), Random Forest, and K-Nearest Neighbors (KNN), for diabetes prediction on the DiaBD dataset (5,288 patient records from Bangladesh). To address the pronounced class imbalance (6.5% diabetic vs. 93.5% non-diabetic), we apply the Synthetic Minority Over-sampling Technique (SMOTE) to the training data and assess performance using accuracy, precision, recall, F1-score, and ROC-AUC. Experimental results show that Random Forest yields the best overall performance after SMOTE, achieving 93.67% accuracy and 0.8798 ROC-AUC, outperforming the remaining traditional baselines. Feature-importance analysis further indicates that hypertension, glucose-related measures, and blood pressure are the most informative predictors. These findings support the practical use of traditional, interpretable machine learning models for diabetes risk assessment in resource-constrained healthcare settings.
  • A multi-stage stacking framework for accurate and interpretable life expectancy modeling

    Chinthaginjala R., Tera S.P., Natha P., Srinivasulu A., Al-Turjman F., Mohammad F.

    Article, PLOS One, 2026, DOI Link

    View abstract ⏷

    Accurate life-expectancy estimation is critical for evidence-based health policy, monitoring Sustainable Development Goal 3 (SDG 3), and guiding global resource allocation. Existing machine-learning approaches typically provide point predictions with limited interpretability and uncertainty quantification. To address these limitations, we propose NEXUS-LE (Neuro-Symbolic Explainable Unified Stacking for Life Expectancy), a unified ensemble framework that integrates predictive accuracy, calibrated uncertainty, and policy-level explainability. The model is trained on a global dataset comprising 22,050 country-year observations across 193 countries (2000-2021) and 150 World Health Organization indicators. The framework combines leave-one-out encoding, principal component analysis, and K-Means-based manifold features with SHAP-guided polynomial expansion and a three-level stacking architecture, followed by a LightGBM residual correction and split-conformal calibration. On a held-out test set (n = 3,308), the model achieves R2 = 0.9878, RMSE = 1.0665 years, MAE = 0.6185 years, and MAPE = 0.9239%. Conformal prediction attains 95.04% empirical coverage at the 95% nominal level with a 90% interval width of 3.32 years. Interpretability analysis shows that demographic and structural factors contribute 96.3% of total attribution, with consistent non-linear effects across policy domains. The proposed framework provides a reliable and interpretable solution for life-expectancy prediction in global health applications.
  • Advancing quantum machine learning from conceptual design to practical use

    Tera S.P., Chinthaginjala R., Zhao X., Hamdi M.

    Review, Expert Systems with Applications, 2026, DOI Link

    View abstract ⏷

    This study presents an integrated assessment of quantum machine learning (QML) that combines quantum-computing foundations, algorithmic design, hardware constraints, and empirical evidence into a single, coherent framework. Drawing on a PRISMA-compliant systematic review of 142 peer-reviewed articles published between 2016 and 2025, the study analyzes how QML methods are actually performing on current noisy intermediate-scale quantum (NISQ) devices and against well-tuned classical baselines. A seven-dimensional taxonomy is introduced that organizes the QML design space along data encoding, model paradigms (QSVM, QPCA, QNN, VQC, QBM), training and optimization, hardware platforms, application domains, evaluation protocols, and technology-readiness levels, with method-selection guidelines for each axis. For the five core QML model families, the survey provides end-to-end workflows and comparative evidence tables reporting datasets, hyperparameters, resource usage (qubits, circuit depth, shots, wall-clock time), performance metrics with uncertainty, and explicit advantage classifications. The results show that, under fair comparisons with optimized classical methods and full resource accounting, QML currently yields parity at best—and often classical superiority—for supervised learning on classical data, while the most credible near-term benefits arise in quantum-native domains such as quantum chemistry and many-body physics. The study further proposes an eight-criterion quantum-advantage evaluation framework and a challenge taxonomy that quantify key obstacles—including decoherence, barren plateaus, data-loading overhead, classical competition, and scalability limits—and outline realistic pathways toward future fault-tolerant, quantum-native QML applications.
  • Hybrid AI and semiconductor approaches for power quality improvement

    Chinthaginjala R., Srinivasulu A., Agrawal A., Kim T.H., Tera S.P., Ahmad S.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    This research presents a novel approach to improving electric power quality using semiconductor devices by integrating Machine Learning (ML), Deep Learning (DL), and advanced control strategies. The research addresses key power quality challenges - including voltage sags, swells, harmonics, and transient disturbances - through a data-driven framework that combines traditional control techniques with adaptive learning models. A variety of algorithms, including Support Vector Machines (SVM), Random Forests, Neural Networks, Convolutional Neural Networks (CNN), and Long Short-Term Memory (LSTM) networks, were tested using real-time data. The results showed notable differences in performance, with deep learning models, especially LSTM, proving to be more accurate and dependable in identifying and forecasting power quality issues. In contrast, traditional ML models like SVM and Random Forest had difficulties with class imbalance, resulting in lower precision and recall. DL models, however, managed these challenges effectively, with CNN achieving a precision of 91.8% and LSTM attaining perfect accuracy (100%) and a recall of 94.5%. The study also highlighted the complications of handling imbalanced datasets, as indicated by classification warnings, emphasizing the importance of improved preprocessing and model adjustments for reliable predictions. The execution times varied significantly, with traditional control systems being faster but less capable in identifying complex patterns compared to the computationally intensive DL models. These findings highlight the promise of hybrid systems that integrate both traditional and data-driven control strategies to achieve adaptive and dependable power quality management. Both simulations and real-world experiments support the effectiveness of this hybrid method, suggesting a strong foundation for intelligent power quality solutions in future smart grid applications. The research concludes that although deep learning models offer superior accuracy and predictive power for complex power quality scenarios, practical deployment requires careful balancing of computational demands and addressing class distribution challenges.
  • Toward 6G: An Overview of the Next Generation of Intelligent Network Connectivity

    Prasad Tera S., Chinthaginjala R., Pau G., Hoon Kim T.

    Review, IEEE Access, 2025, DOI Link

    View abstract ⏷

    The development of 6G networks represents a groundbreaking leap in mobile communication, targeting the creation of an Intelligent Network of Everything that seamlessly integrates advanced technologies such as Artificial Intelligence (AI), Machine Learning (ML), and the Internet of Everything (IoE). This next-generation network is projected to begin standardization in 2025, with commercial deployment anticipated by 2030. Building on the foundation of its predecessors, 6G aims to deliver ultra-reliable, low-latency, and high-speed communication essential for applications like autonomous systems, immersive virtual environments, and smart cities. This article provides a comprehensive overview of 6G, articulating its vision and identifying the core technologies that will enable its transformative capabilities. The key contributions of this work include a detailed exploration of prospective 6G applications and use cases, such as autonomous systems and integrated communication-sensing scenarios. Additionally, it identifies major challenges - such as advanced coding schemes, energy management, and security - and presents a roadmap for future research in these critical areas. The study also reviews potential coding and modulation techniques, such as non-binary codes and lattice codes, assessing their suitability for 6G's stringent performance requirements. Security and privacy considerations are also covered, proposing a robust architecture across all network layers to address emerging threats. Furthermore, the article compiles a literature review on 6G visions and surveys, providing valuable insights into the current state of research, highlighting gaps, and guiding future studies. Through the exploration of spectrum advancements, antenna technologies, network intelligence, and AI/ML integration, this work establishes a clear vision for how 6G can reshape global communication infrastructure and drive innovation in a hyper-connected world.
  • Exploring the Mathematical Foundations of Generative AI Models: VAEs, GANs, Transformers, and DMs

    Prasad Tera S., Ravikumar C.V., Natha P., Pau G.

    Article, IEEE Access, 2025, DOI Link

    View abstract ⏷

    Generative Artificial Intelligence (GAI) has rapidly advanced, revolutionizing content creation across diverse domains, including text, image, audio, and video synthesis. Generative models, including Transformers, Variational Autoencoders (VAEs), Diffusion Models, and Generative Adversarial Networks (GANs) are built on strong mathematical principles that support their ability to learn intricate data patterns and produce high-quality synthetic outputs. This article presents a comprehensive exploration of the mathematical principles that underpin these models, including key concepts such as probabilistic inference, minimax optimization, self-attention mechanisms, and diffusion processes. By focusing on foundational mathematical constructs—such as Evidence Lower Bound (ELBO) optimization in VAEs, adversarial training objectives in GANs, scaled dot-product attention in Transformers, and iterative denoising in Diffusion Models—this work elucidates how each model leverages these principles to achieve generative capabilities. The study highlights the application of these mathematical foundations across varied generative tasks and examines their impact on real-world challenges in sectors like healthcare, media, and scientific research. Additionally, this article addresses the growing need for ongoing mathematical refinement and innovation in GAI to tackle emerging ethical, privacy, and security challenges. Through this examination, we aim to provide researchers, practitioners, and policymakers with a deep understanding of the mathematical basis for modern generative models, guiding future developments in GAI.
  • Improving CNN predictive accuracy in COVID-19 health analytics

    Kim T.-H., Srinivasulu A., Chinthaginjala R., Dhakshayani J., Zhao X., Obaidur Rab S., Tera S.P.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    The COVID-19 pandemic has underscored the critical necessity for robust and accurate predictive frameworks to bolster global healthcare infrastructures. This study presents a comprehensive examination of convolutional neural networks (CNNs) applied to the prediction of COVID-19-related health outcomes, with an emphasis on core challenges, methodological constraints, and potential remediation strategies. Our investigation targets two principal aims: the identification of COVID-19 infections through chest radiographic imaging, specifically X-rays, and the prognostication of disease severity by integrating clinical parameters and electronic health records. Utilizing a multidimensional dataset encompassing demographic, clinical, and radiological information, we evaluated the efficacy of CNN architectures in forecasting patient prognoses. The CNN model attained an accuracy of 97.2%, reflecting its capability while simultaneously revealing significant challenges, including limited and imbalanced data, as well as difficulties in model interpretability. Principal limitations identified comprise overfitting, data heterogeneity, and the imperative for model adaptability amid evolving SARS-CoV-2 variants. To mitigate these issues, we propose strategies such as data augmentation, transfer learning, ensemble modeling, and enhancements in explainability, which collectively demonstrated improvements in predictive performance and theoretical robustness. This work highlights the imperative for continuous model refinement and the integration of domain-specific expertise to elevate the reliability and applicability of CNN-based prognostic tools for COVID-19 healthcare analytics. Our empirical results indicate that the CNN achieved a precision of 96.8%, an F1-score of 97.2%, and an AUC-ROC of 0.987, underscoring its effectiveness in detecting and classifying COVID-19 cases. These insights provide valuable directions for researchers and clinicians, fostering data-driven approaches in the management and prediction of COVID-19 health outcomes.
  • Boosting skin cancer diagnosis accuracy with ensemble approach

    Natha P., Tera S.P., Chinthaginjala R., Rab S.O., Narasimhulu C.V., Kim T.H.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    Skin cancer is common and deadly, hence a correct diagnosis at an early age is essential. Effective therapy depends on precise classification of the several skin cancer forms, each with special traits. Because dermoscopy and other sophisticated imaging methods produce detailed lesion images, early detection has been enhanced. It’s still difficult to analyze the images to differentiate benign from malignant tumors, though. Better predictive modeling methods are needed since the diagnostic procedures used now frequently produce inaccurate and inconsistent results. In dermatology, Machine learning (ML) models are becoming essential for the automatic detection and classification of skin cancer lesions from image data. With the ensemble model, which mix several ML approaches to take use of their advantages and lessen their disadvantages, this work seeks to improve skin cancer predictions. We introduce a new method, the Max Voting method, for optimization of skin cancer classification. On the HAM10000 and ISIC 2018 datasets, we trained and assessed three distinct ML models: Random Forest (RF), Multi-layer Perceptron Neural Network (MLPN), and Support Vector Machine (SVM). Overall performance was increased by the combined predictions made with the Max Voting technique. Moreover, feature vectors that were optimally produced from image data by a Genetic Algorithm (GA) were given to the ML models. We demonstrate that the Max Voting method greatly improves predictive performance, reaching an accuracy of 94.70% and producing the best results for F1-measure, recall, and precision. The most dependable and robust approach turned out to be Max Voting, which combines the benefits of numerous pre-trained ML models to provide a new and efficient method for classifying skin cancer lesions.
  • Deep learning approach for automated hMPV classification

    Tera S.P., Chinthaginjala R., Shahzadi I., Natha P., Rab S.O.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    Human metapneumovirus (hMPV) is a significant cause of respiratory illness, particularly in children, elderly individuals, and immunocompromised patients. Despite its clinical relevance, hMPV poses diagnostic challenges due to its symptom similarity with other respiratory illnesses, such as influenza and respiratory syncytial virus (RSV), and the lack of specialized detection systems. Traditional diagnostic methods are often inadequate for providing rapid and accurate results, particularly in low-resource settings. This study proposes a novel deep learning framework, referred to as hMPV-Net, which leverages Convolutional Neural Networks (CNNs) to facilitate the precise detection and classification of hMPV infections. The CNN model is designed to perform binary classification by differentiating between hMPV-positive and hMPV-negative cases. To address the lack of real-world patient data, simulated image datasets were used for model training and evaluation, allowing the model to generalize to various clinical scenarios. A key challenge in developing this model is the imbalance within the dataset, where hMPV-positive cases are often underrepresented. To mitigate this, the framework incorporates advanced techniques such as data augmentation, weighted loss functions, and dropout regularization, which help to balance the dataset, improve model robustness, and enhance classification accuracy. These techniques are crucial in addressing issues such as overfitting and generalization, which are common when working with limited datasets in medical imaging tasks. The dataset used for model training and testing consists of 10,000 samples, with an equal distribution of hMPV-positive and hMPV-negative cases. Experimental results demonstrate that the hMPV-Net model achieves a high test accuracy of 91.8%, along with impressive test precision, recall, and F1-score values around 92%. These metrics indicate that the model performs exceptionally well in classifying both hMPV-positive and hMPV-negative cases. Furthermore, the model exhibits superior computational efficiency, requiring only 3.2 GFLOPs, which is significantly lower than other state-of-the-art models such as ResNet-50 and VGG-16. This reduction in computational cost makes the model suitable for deployment in resource-constrained healthcare environments, where computing power and infrastructure may be limited.
  • COVID-19 health data prediction: a critical evaluation of CNN-based approaches

    Kim T.H., Chinthaginjala R., Srinivasulu A., Tera S.P., Rab S.O.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    The COVID-19 pandemic has significantly accelerated the demand for accurate and efficient prediction models to support effective disease management, containment strategies, and informed decision-making. Predictive models capable of analyzing complex health data are essential for monitoring disease trends, evaluating risk factors, and optimizing resource allocation during the pandemic. Among various machine learning approaches, convolutional neural networks (CNNs) have emerged as powerful tools due to their ability to process large volumes of high-dimensional health data, such as medical images, time-series data, and patient demographics, with impressive precision. This research seeks to systematically examine the challenges and limitations inherent in utilizing CNNs for COVID-19 health data prediction, offering a comprehensive perspective grounded in data science research. Key areas of investigation include issues related to data quality and availability, such as incomplete, noisy, and imbalanced datasets, which often hinder the training of robust models. Additionally, architectural constraints of CNNs, including their sensitivity to hyperparameter tuning and reliance on substantial computational resources, are explored as critical bottlenecks that impact scalability and efficiency. A significant focus is placed on generalization challenges, where models trained on specific datasets struggle to adapt to unseen data from diverse populations or clinical settings, limiting their applicability in real-world scenarios. The study further highlights a reported accuracy of 63%, underscoring the need for improved methodologies to enhance model performance and reliability. By addressing these challenges, this research aims to provide actionable insights and practical recommendations to optimize the use of CNNs for COVID-19 health data prediction. In particular, the study emphasizes the importance of incorporating advanced strategies such as transfer learning, data augmentation, and regularization techniques to overcome dataset limitations and enhance model robustness. The integration of multimodal approaches combining medical images with auxiliary data, such as patient demographics and laboratory results, is proposed to improve contextual understanding and diagnostic precision. Finally, the research underscores the necessity of interdisciplinary collaboration, leveraging domain expertise from data scientists, healthcare professionals, and epidemiologists to develop holistic solutions for tackling the complexities of COVID-19 prediction. By shedding light on the limitations and potential of CNNs in this domain, this study aims to guide researchers and practitioners in making informed decisions about model design, implementation, and optimization. Ultimately, it contributes to advancing AI-driven diagnostics and predictive modeling for COVID-19 and other public health crises, fostering the development of scalable and reliable tools for better healthcare outcomes.
  • Deep learning assisted LDPC decoding for 5G IoT networks in fading environments

    Prasad S., Chinthaginjala R., Al-Turjman F., Ahmad S.

    Article, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    With the deployment of 5G networks, the Internet of Things (IoT) has experienced a transformative boost, enabling higher data rates, reduced latency, and the connection of millions of devices across applications like smart cities, healthcare, and industrial automation. However, in real-world scenarios, the performance of Low-Density Parity-Check (LDPC) codes, the preferred channel coding scheme in 5G, is severely affected by noise and fading environments, particularly colored noise, which distorts signals over certain frequency bands. Colored noise introduces correlation in the interference, unlike white noise, thereby posing a challenge in decoding, especially in fading channels such as Rayleigh, Rician, and Nakagami-m. In this work, we propose a novel approach that combines the Iterative Offset Min-Sum (OMS) algorithm with a Convolutional Neural Network (CNN) to enhance LDPC decoding efficiency in 5G-enabled IoT networks. Our proposed OMS-CNN hybrid architecture addresses the limitations imposed by colored noise in fading channels by employing deep learning techniques for accurate noise estimation and mitigation. Furthermore, the OMS algorithm mitigates the overestimation of noise correction, refining the output in iterative decoding steps. Through comprehensive simulations, the OMS-CNN decoder demonstrates substantial improvements over traditional decoding approaches. Specifically, it achieves a performance enhancement of 2.7 dB at a bit error rate (BER) of across a range of fading channels. The study examines the decoder’s performance in environments characterized by Rayleigh, Rician, and Nakagami-m fading models, highlighting the robustness of the proposed solution under different channel conditions. Additionally, this research explores the influence of parameters such as the correlation coefficient of the noise, the scaling factor in the cost function, and the number of iterations between the CNN and OMS decoding steps.
  • Correction: Deep learning assisted LDPC decoding for 5G IoT networks in fading environments (Scientific Reports, (2025), 15, 1, (37469), 10.1038/s41598-025-21382-y)

    Tera S.P., Chinthaginjala R., Al-Turjman F., Ahmad S.

    Erratum, Scientific Reports, 2025, DOI Link

    View abstract ⏷

    Correction to: Scientific Reportshttps://doi.org/10.1038/s41598-025-21382-y, published online 27 October 2025 The original version of this Article contained an error in the spelling of the author Sivarama Prasad Tera which was incorrectly given as Sivarama Prasad. In addition, Sivarama Prasad Tera was incorrectly affiliated with ‘Department of Electronics and Electrical Engineering, Indian Institute of Technology, Guwahati, Assam 781039, India’. The correct affiliation is ‘School of Electrical Engineering, Kore University of Enna, Enna, Italy’. The original Article has been corrected.
  • Deep Learning Approach for Efficient 5G LDPC Decoding in IoT

    Tera S.P., Chinthaginjala R.V., Natha P., Ahmad S., Pau G.

    Article, IEEE Access, 2024, DOI Link

    View abstract ⏷

    The tremendous progress of 5G technology has transformed the landscape of the Internet of Things (IoT), allowing for fast data speeds, low delay, and widespread connection that is crucial for a variety of applications, including smart cities and industrial automation. In the context of 5G enabled IoT networks, colored noise introduces varying levels of interference across different frequency bands, which can significantly degrade the performance of 5G LDPC decoding. This paper presents a novel Deep learning approach for 5G channel LDPC code decoding tailored for next-generation IoT applications. The proposed method integrates an Iterative Normalized Min-Sum (NMS) algorithm with a Convolutional Neural Network (CNN) to enhance the performance of LDPC decoding in the presence of colored noise, a common interference in real-world communication channels. Through extensive simulations and analysis, our approach demonstrates a significant performance improvement, achieving a 3.8 dB enhancement at a Bit error rate of 10-6. This is achieved by accurately estimating and mitigating channel noise, thereby ensuring reliable data transmission for critical IoT applications. The findings indicate that our approach to decoding technique not only enhances error correction capabilities but also adapts to varying channel conditions, optimizing IoT network performance and efficiency. This research contributes a robust solution to the challenges posed by colored noise in 5G-enabled IoT networks, promoting the deployment of more reliable and efficient IoT systems.
  • CNN-Based Approach for Enhancing 5G LDPC Code Decoding Performance

    Tera S.P., Chinthaginjala R., Natha P., Pau G., Dhanamjayulu C., Mohammad F.

    Article, IEEE Access, 2024, DOI Link

    View abstract ⏷

    This paper presents the novel Stochastic decoding-convolutional neural network (SD-CNN) structure, with the goal of enhancing 5G LDPC code's decoding efficiency in the presence of correlated noise of the channel. Applying the stochastic approach acts as an alternate technique to fixed-point LDPC decoding to enhance the decoder's hardware efficiency. In order to improve the efficacy of the decoder, we adopted deep learning method such as Convolutional neural network (CNN). CNNs can be employed for denoising purposes in communication systems, where signals may be compromised by diverse forms of noise while being transmitted, with the aim of enhancing signal quality and dependability. The SD-CNN architecture combines a trained CNN with a stochastic decoder of 5G LDPC codes, thereby utilizing the CNN's capability to accurately estimate channel noise and, consequently, enhance the error correction capabilities of the decoder. The generated output of the trained CNN is then fed back into the stochastic decoder, creating an iterative process between the SD and CNN that ultimately leads to superior decoding performance. For 5G LDPC code word length N = 3808 , with a base code rate R = 1/3, the suggested SD-CNN architecture achieves a BER of 10-6 at 0.6 dB of SNR per bit in the strong correlation of channel noise condition, in comparison to SD, which achieves a BER of 10-6 at 3.5 dB of SNR per bit. The results demonstrate that there is a 2.9 dB improvement.
  • A Flexible FPGA-Based Stochastic Decoder for 5G LDPC Codes

    Tera S.P., Alantattil R., Paily R.

    Article, Electronics (Switzerland), 2023, DOI Link

    View abstract ⏷

    Iterative stochastic decoding is an alternative to standard fixed-point decoding of low-density parity check (LDPC) codes that can be used to minimize inter-node routing. A flexible field-programmable gate array (FPGA)-based stochastic decoding (SD) hardware architecture is presented in this paper. The architecture is designed to decode different code rates of LDPC codes that comply with the fifth-generation (5G) New Radio (NR) standard. This decoder’s runtime flexibility is desirable as it switches to a better-performing code rate automatically based on the channel conditions without the extra time needed to reprogram the FPGA. An offline design method is implemented to generate the hardware description language (HDL) code description of the decoder for the required code rate set, which is further synthesized and integrated into a Xilinx Kintex-7-series FPGA board to determine the hardware resource utilisation and processing throughput. Synopsys design tools were employed during both the simulation and synthesis stages in combination with TSMC 65 nm CMOS standard cell technology to facilitate comparative analysis. Compared with state-of-the-art designs, the proposed architecture reduces hardware utilization by up to 26% and increases energy efficiency by 52%.
  • Optimal implementation of UART-SPI Interface in SoC

    Praveen Blessington T., Bhanu Murthy B., Ganesh G.V., Prasad T.S.R.

    Conference paper, 2012 International Conference on Devices, Circuits and Systems, ICDCS 2012, 2012, DOI Link

    View abstract ⏷

    This paper details the design and implementation of SoC's UART-SPI Interface. The UART-SPI interface provides usage for the universal asynchronous receiver/transmitter (UART) to serial peripheral interface (SPI). This interface can be used to communicate to SPI slave devices from a PC with UART port. The interface consists of three blocks: the UART interface, the UART-to-SPI interfacing block and the SPI Master interface. © 2012 IEEE.
Contact Details

sivaramaprasad.t@srmap.edu.in

Scholars