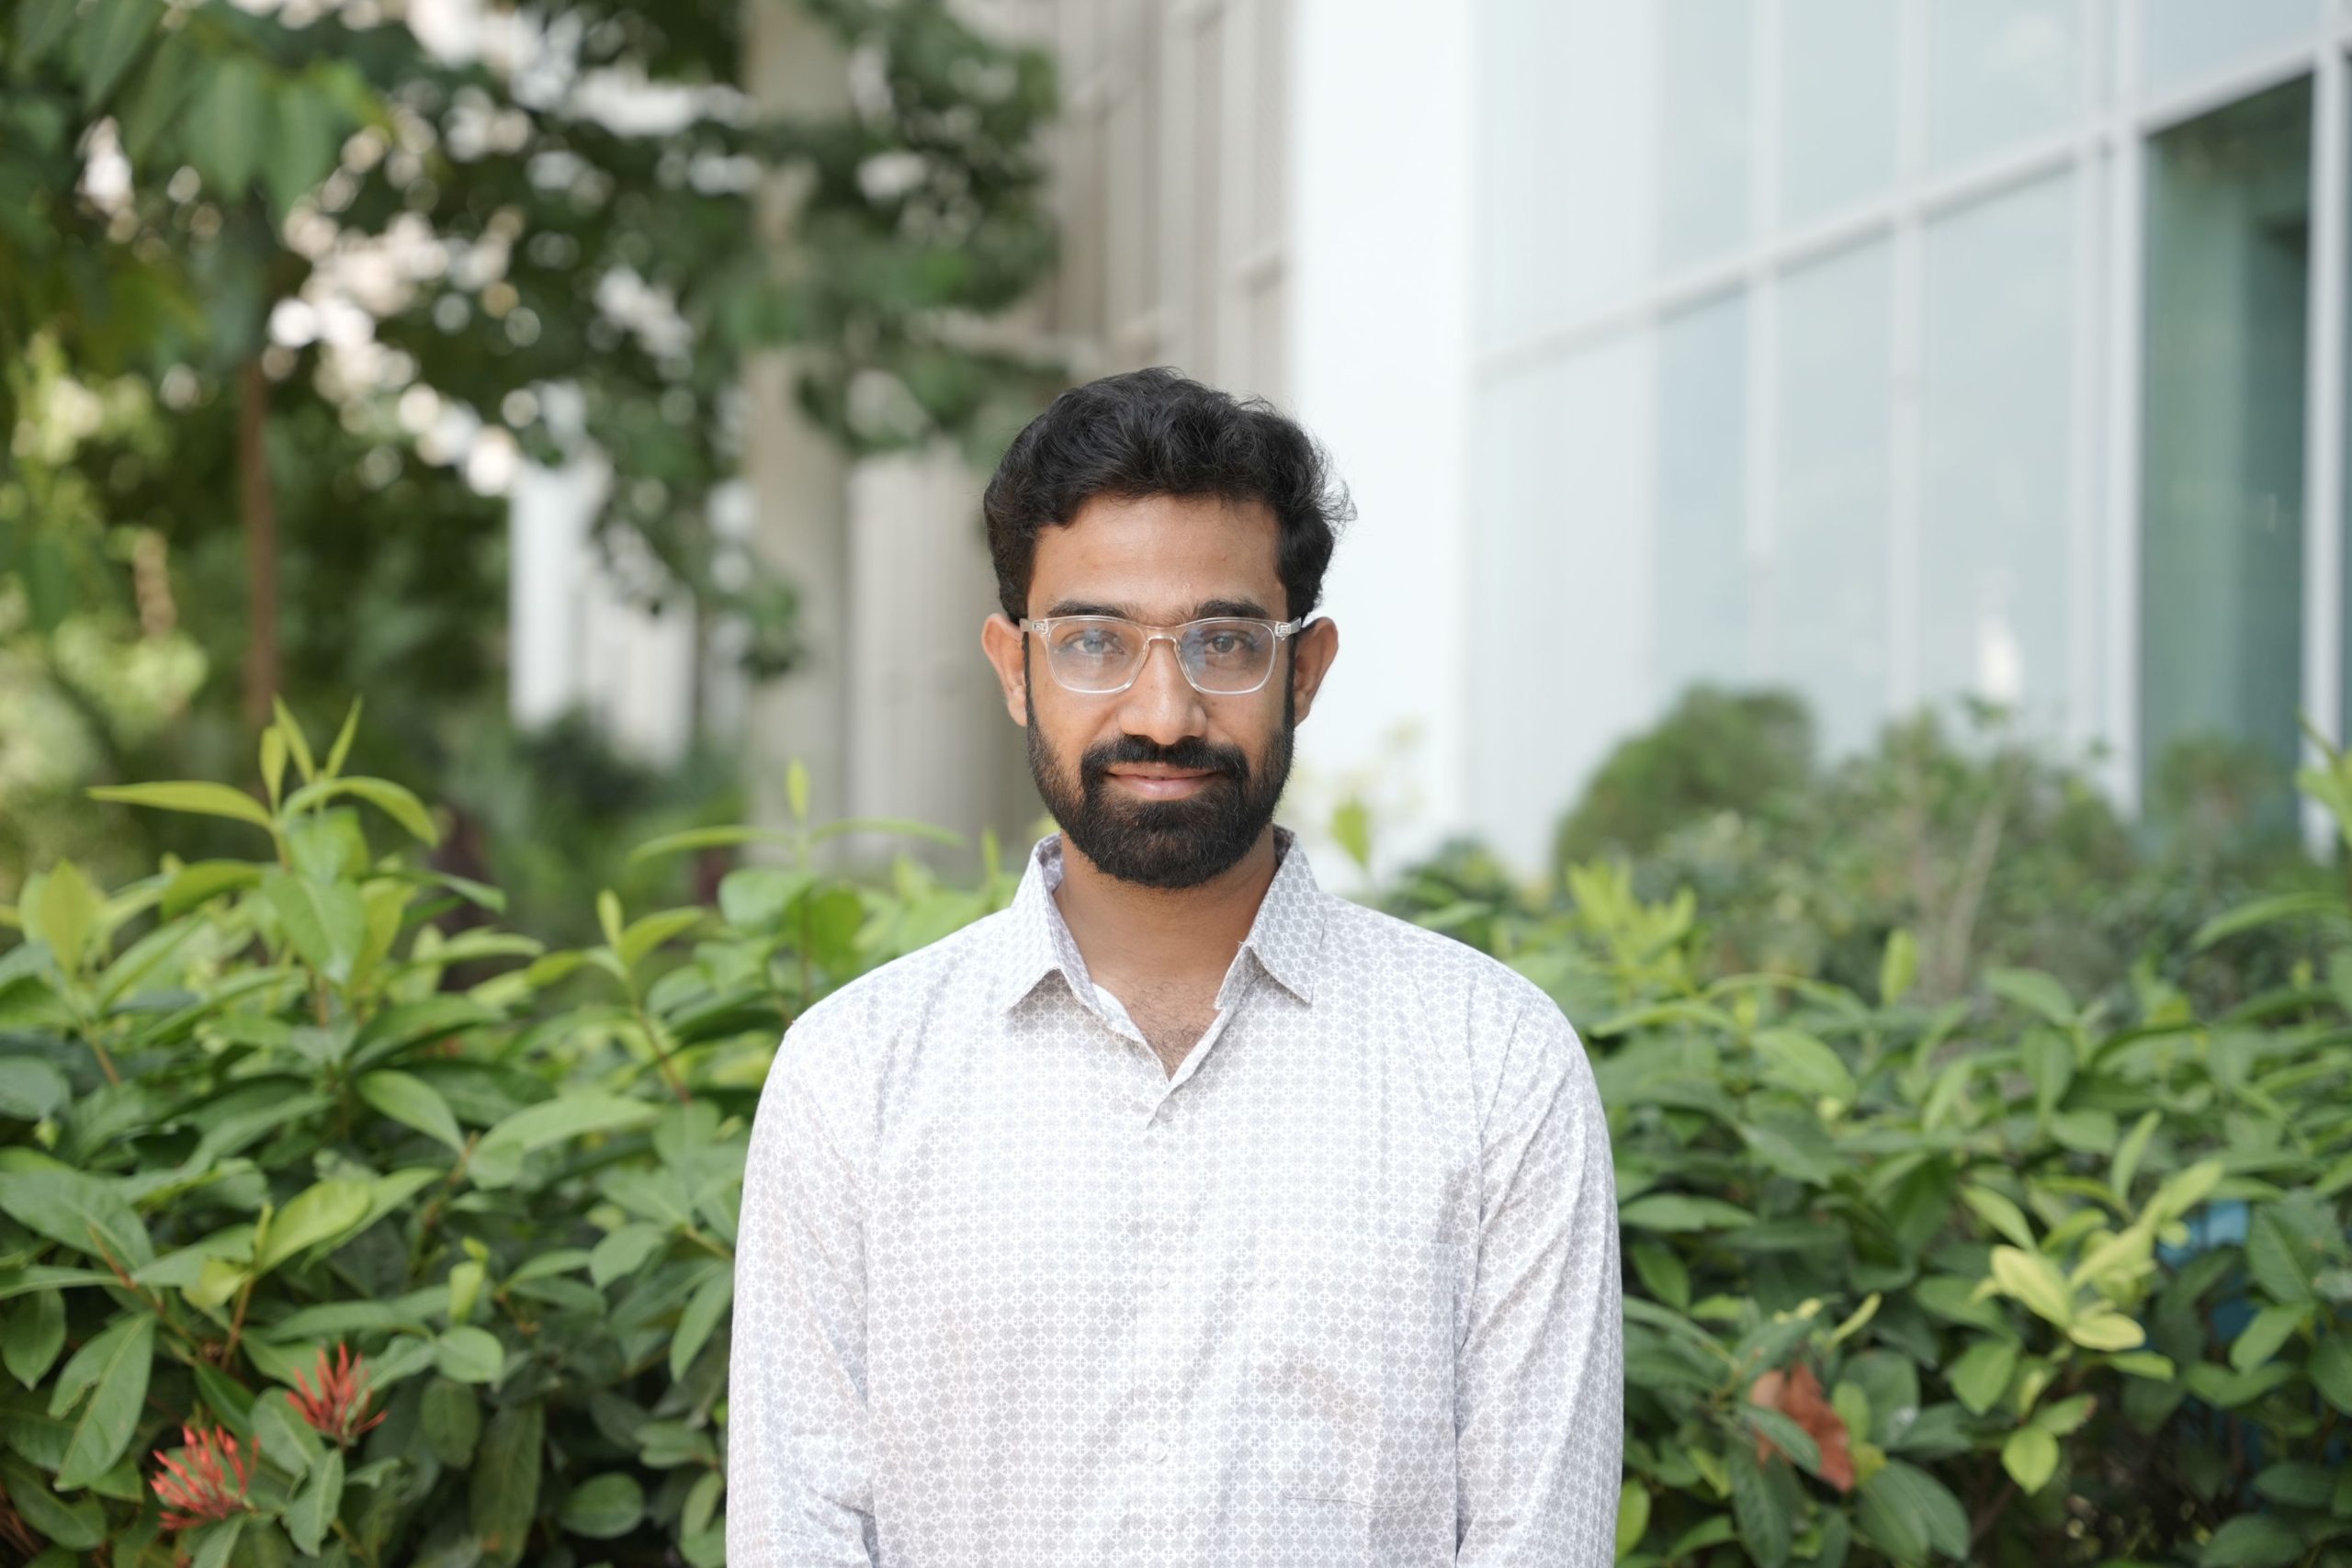
Faculty Dr Suman Nandi
Dr Suman Nandi

Dr Suman Nandi

Assistant Professor

Department of Computer Science and Engineering

Contact Details

suman.n@srmap.edu.in

Office Location

Homi J Bhabha Block, Level 3, ALC

Social Links

Education

2026
Ph.D. in Computer Science and Engineering
National Institute of Technology Durgapur, West Bengal
2019
M.Tech. in Computer Science and Engineering
Maulana Abul Kalam Azad University of Technology, West Bengal
2016
M.Sc. in Computer Science
Vidyasagar University, West Bengal
2014
B.Sc. in Computer Science
Vidyasagar University, West Bengal

Personal Website

Experience

  • Served as a Junior Research Fellow (SERB-DST Funded Project) at the Department of Computer Science and Engineering, NITTTR Kolkata, conducting large-scale in silico analysis of COVID-19 genomic sequences.

Research Interest

  • Research interests include Complex Network Analysis, Social Network Analysis, Influential Spreader Identification, Influence Maximization, and Graph Representation Learning.

Awards

  • Selected for the Erasmus+ International Credit Mobility (ICM) Programme for collaborative research at the Polytechnic Institute of Castelo Branco, Portugal (March–June 2023).
  • Awarded the GATE Scholarship by the Ministry of Human Resource Development (MHRD), Government of India, during the M.Tech. programme (2017–2019).

Memberships

Publications

  • Community-based voting approach to enhance the spreading dynamics by identifying a group of influential spreaders in complex networks

    Nandi S., Curado Malta M., Maji G., Dutta A.

    Article, Journal of Computational Science, 2025, DOI Link

    View abstract ⏷

    Exploring a group of influential spreaders to acquire maximum influence has become an emerging area of research in complex network analysis. The main challenge of this research is to identify the group of important nodes that are scattered broadly, such that the propagation ability of information is maximum to a network. Researchers proposed many centrality-based approaches with certain limitations to identify the influential nodes (spreaders) considering different properties of the networks. To find a group of spreaders, the VoteRank (a voting mechanism) based method produces effective results with low time complexity, where in each iteration, the node votes for its neighbors by its voting capability, and the node obtaining the maximum vote score is identified as an influential spreader. The major loophole of existing VoteRank methods is measuring the voting capability based on the degree, k-shell index, or contribution of neighbors methods, which does not efficiently identify the spreaders from the diverse regions based on their spreading ability. In this paper, we propose a novel Community-based VoteRank method (CVoteRank) to identify a group of influential spreaders from diverse network regions by which the diffusion process is enhanced. Firstly, we measure every node's spreading ability based on intra- and inter-connectivity structure in a community, which signifies the local and global importance of the node. To identify the seed nodes, we assign the spreading ability to that node's voting capability and iteratively calculate the voting score of a node based on its neighboring voting capability and its spreading ability. Then, the node acquiring the maximum voting score is identified as the influential spreader in each iteration. Finally, to solve the problem of influence overlapping, CVoteRank reduces the voting capability of the neighboring nodes of the identified spreader. The efficiency of CVoteRank is evaluated and compared with the different state-of-the-art methods on twelve real networks. Utilizing the stochastic susceptible–infected–recovered epidemic method, we calculate the infected scale, final infected scale, and the average shortest path length among the identified spreaders. The experimental results show that CVoteRank identifies the most efficient spreaders with the highest spreading ability within a short period and the maximum reachability, and the identified spreaders are situated at diverse portions of the networks.
  • IC-SNI: measuring nodes’ influential capability in complex networks through structural and neighboring information

    Nandi S., CuradoMalta M., Maji G., Dutta A.

    Article, Knowledge and Information Systems, 2025, DOI Link

    View abstract ⏷

    Influential nodes are the important nodes that most efficiently control the propagation process throughout the network. Among various structural-based methods, degree centrality, k-shell decomposition, or their combination identify influential nodes with relatively low computational complexity, making them suitable for large-scale network analysis. However, these methods do not necessarily explore nodes’ underlying structure and neighboring information, which poses a significant challenge for researchers in developing timely and efficient heuristics considering appropriate network characteristics. In this study, we propose a new method (IC-SNI) to measure the influential capability of the nodes. IC-SNI minimizes the loopholes of the local and global centrality and calculates the topological positional structure by considering the local and global contribution of the neighbors. Exploring the path structural information, we introduce two new measurements (connectivity strength and effective distance) to capture the structural properties among the neighboring nodes. Finally, the influential capability of a node is calculated by aggregating the structural and neighboring information of up to two-hop neighboring nodes. Evaluated on nine benchmark datasets, IC-SNI demonstrates superior performance with the highest average ranking correlation of 0.813 with the SIR simulator and a 34.1% improvement comparing state-of-the-art methods in identifying influential spreaders. The results show that IC-SNI efficiently identifies the influential spreaders in diverse real networks by accurately integrating structural and neighboring information.
  • Exploring emerging spreaders through GCN-based link prediction and a novel centrality method

    Nandi S., Maji G., Dutta A.

    Conference paper, International Conference on Communication Systems and Networks, COMSNETS, 2025, DOI Link

    View abstract ⏷

    Exploring influential spreaders and predicting missing links in complex networks is essential for understanding and effectively controlling network dynamics. This paper presents a Graph Convolutional Network (GCN)-based link prediction method to estimate the probability of future link formation. We incorporate node features that capture local and global topological connectivity structures and feed these into the GCN model, where convolutional layers aggregate neighboring information and transform node features. This approach enables the model to capture structural patterns by integrating local and global information from neighboring nodes. In the final layer, the GCN model computes a prediction score representing the likelihood of an edge's existence, using insights gained during training. Finally, considering the predicted links, we update the network structure and introduce a novel centrality method called Emerging Spreader Centrality (ESC) to identify emerging spreaders within this augmented network. We conduct two separate experiments to evaluate the performance of the GCN-based link prediction and the ESC method, comparing their effectiveness with various state-of-the-art methods. Results demonstrate that our approach not only effectively predicts future links but also identifies emerging spreaders in the augmented networks.
  • Identifying vital spreaders in multiplex networks: measurement of layer dominance and a closeness-based layer gravity method

    Nandi S., Maji G., Dutta A.

    Article, Journal of Supercomputing, 2025, DOI Link

    View abstract ⏷

    The exploration of multiplex networks has become an emerging field of research due to the existence of different layers with diverse connectivity structures in almost every real network. Effectively managing a multiplex network is challenging, requiring the identification of vital spreaders (i.e., nodes) by measuring their importance. After reviewing the existing studies, it becomes clear that the dominance of individual layers has not been systematically evaluated in isolation in multiplex networks. In this study, we present a novel approach to measure the dominance of individual layers depending on two distinct parameters: node activeness and edge activeness. After that, we calculate the centrality value for each node on a per-layer basis and construct a centrality vector based on existing centrality methods and a novel Closeness-based Layer Gravity (CLG) method. Finally, the vital spreaders are identified by evaluating the importance of nodes through a mapping technique that aggregates the dominance of the layers with centrality values of the nodes from the respective layers. This proposed framework independently measures layer dominance and identifies vital spreaders, making it well suited for distributed and high-performance computing environments, and ensuring scalability across large multiplex networks. The performance of our proposed method is evaluated against the multiplex-based SIR epidemic simulator, and we observe that amalgamating our proposed layer dominance concept with the CLG method effectively identifies vital nodes, achieving a maximum average ranking similarity of 80.93% across various percentages of identified spreaders, considering eight real multiplex networks. By evaluating network robustness through the normalized LCC (Largest Connected Component) value after removing various percentages of identified spreaders, our method achieves the lowest average normalized LCC value of 0.751, outperforming state-of-the-art approaches.
  • Local Closeness Gravity Model to Identify the Vital Nodes in Complex Networks

    Nandi S., Dutta A.

    Conference paper, 2024 16th International Conference on COMmunication Systems and NETworkS, COMSNETS 2024, 2024, DOI Link

    View abstract ⏷

    In complex network analysis, identifying the viral nodes is a major concern of the research domain by which any kind of information or infection is controlled throughout the entire network. Several algorithms have been developed over the past few years to identify the viral nodes (influential spreaders) considering many properties of the network. Among them, some authors proposed gravity-based centrality to identify the vital nodes based on the law of gravity with certain limitations. The major limitation of existing gravity-based methods is the mass of the object (i.e. node) is considered as the degree or kshell index only, which does not always signify the spreading ability of the nodes. To address this research challenge, we propose an innovative Local Closeness Gravity method (named LCG) to measure the influential ability of individual nodes, facilitating the identification of the vital nodes in the network. To minimize the computational complexity of Closeness centrality, at first, we measure the local Closeness centrality of individual nodes considering all the nodes residing in the truncation radius. Thereafter we introduce a new parameter 'information sharing ability' based on connectivity strength to measure the distance between the nodes. Finally, the influential ability of each node is measured based on the gravity model considering the local closeness centrality, kshell index, and the distance. The efficiency of LCG is compared with the existing baseline centrality methods by using the Susceptible-Infectious-Recovered (SIR) simulator. The correlation between the LCG method and the baseline centrality methods with the SIR method is compared by Kendalls' tau method considering various infection probabilities and various percentages of seed nodes respectively. The ranking uniqueness of the LCG method and the baseline centrality methods are also measured by the monotonicity metrics. Through the obtained results and various analyses, it becomes evident that the LCG method adeptly discerns the vital nodes within the networks.
  • CCC: A Spreader Selection Approach to Control Spreading Dynamics in Complex Networks

    Nandi S., Mandal D., Dutta A.

    Conference paper, Proceedings - 2024 IEEE/WIC International Conference on Web Intelligence and Intelligent Agent Technology, WI-IAT 2024, 2024, DOI Link

    View abstract ⏷

    Due to the diverse structure and varying sizes of networks, identifying super spreaders to limit the spread of information (or infection) has become a significant research challenge. Community-based approaches have shown effectiveness in locating spreaders across diverse network positions. To address gaps in current methods, we propose Community-based Closeness Coreness (CCC), a novel approach for controlling spreading dynamics. CCC first identifies gateway nodes within each community and calculates each node's closeness with these gateway nodes within a truncation radius, reflecting its spreading efficiency. Node coreness is measured by combining the k-shell index and neighbor connectivity, and nodes are ranked based on their aggregated closeness and coreness. Finally, CCC selects spreaders from all communities according to node ranking and community size. Measuring the performance of CCC on six real networks shows that it outperforms baseline methods by identifying super spreaders that enable rapid and extensive diffusion.
  • Identification of Influential Spreaders in a Partially Changed Dynamic Network

    Sarkar M., Nandi S., Maji G., Dutta A.

    Conference paper, 2024 16th International Conference on COMmunication Systems and NETworkS, COMSNETS 2024, 2024, DOI Link

    View abstract ⏷

    Identification of influential spreaders plays a significant role in maximizing or controlling any spreading process in a network. Influential spreaders or influential nodes are the most important nodes in a network that play a key role in spreading information, ideas, or diseases. To identify and rank these important nodes many centrality measures have been proposed by several authors over the past few years. Identifying the major research gap, we observe measuring the node importance in dynamic networks is very limited. Dynamic networks are defined as those networks which change the connectivity structure of the network at every time interval, also known as a time-varying network, as the links are active only at certain points in time. In dynamic networks, ranking the nodes (or finding the most important nodes) becomes computation-heavy if we have to compute the centrality measures on every event (changes in the connectedness of the network). We have considered two easy-to-compute and well-established centrality metrics (K-shell and degree) and attempted to estimate the node ranking by approximating the centrality measures through partial computation for a network that has undergone some changes in the topology (the edge connectivity, some edges become dormant and some new connections between two nodes might have formed). Our primary objective is to avoid computing centrality measures every time, during the changes of connectivity change. We utilize the existing network measures and other parameters along with the changes of connectivity structure to arrive at the updated measures as well as ranking heuristically. It is expected that after every event the topology of the network changes, which in turn would change centrality measures. The focus of the present study is to find out without further re-computation from the beginning the changes in K-shell centrality and degree centrality measures on a particular network model after some changes occur. This proposed method will heuristically estimate the changed k shell values using partial computation.
  • IS-PEW: Identifying Influential Spreaders Using Potential Edge Weight in Complex Networks

    Nandi S., Malta M.C., Maji G., Dutta A.

    Conference paper, Studies in Computational Intelligence, 2024, DOI Link

    View abstract ⏷

    Identifying the influential spreaders in complex networks has emerged as an important research challenge to control the spread of (mis)information or infectious diseases. Researchers have proposed many centrality measures to identify the influential nodes (spreaders) in the past few years. Still, most of them have not considered the importance of the edges in unweighted networks. To address this issue, we propose a novel centrality measure to identify the spreading ability of the Influential Spreaders using the Potential Edge Weight method (IS-PEW). Considering the connectivity structure, the ability of information exchange, and the importance of neighbouring nodes, we measure the potential edge weight. The ranking similarity of spreaders identified by IS-PEW and the baseline centrality methods are compared with the Susceptible-Infectious-Recovered (SIR) epidemic simulator using Kendall’s rank correlation. The spreading ability of the top-ranking spreaders is also compared for five different percentages of top-ranking node sets using six different real networks.
  • Semi-Global Circular Centrality to find Influential Spreaders

    Bhuiya A., Chowdhury K., Nandi S., Dutta A.

    Conference paper, 2023 15th International Conference on COMmunication Systems and NETworkS, COMSNETS 2023, 2023, DOI Link

    View abstract ⏷

    Smartphone use and social network connectivity are becoming more popular. Information sharing is becoming easier and faster. Influential spreaders in social networks play an important role. The identification of these influential nodes becomes a critical issue in social network analysis. Centrality methods are used to identify the influential nodes. There are many centrality methods proposed by researchers. The centrality methods can be classified into mainly four types: local centrality method, global centrality method, semi-global centrality method, and hybrid centrality. However, we have observed that the semi-global centrality method is identifying the ranks of a node based on the few levels of connectivity of a node and has not taken so much time. We are now proposing a new node ranking method called the 'semi-global circular method.' This method finds the top influential spreaders in the dense part of the network. We have applied the susceptible-infected-recovered epidemic model to our toy network to examine the performance of the proposed method. The result shows us that the performance of the proposed method is good.
  • Bioinformatics pipeline unveils genetic variability to synthetic vaccine design for Indian SARS-CoV-2 genomes

    Ghosh N., Saha I., Sharma N., Nandi S.

    Article, International Immunopharmacology, 2022, DOI Link

    View abstract ⏷

    In the worrisome scenarios of various waves of SARS-CoV-2 pandemic, a comprehensive bioinformatics pipeline is essential to analyse the virus genomes in order to understand its evolution, thereby identifying mutations as signature SNPs, conserved regions and subsequently to design epitope based synthetic vaccine. We have thus performed multiple sequence alignment of 4996 Indian SARS-CoV-2 genomes as a case study using MAFFT followed by phylogenetic analysis using Nextstrain to identify virus clades. Furthermore, based on the entropy of each genomic coordinate of the aligned sequences, conserved regions are identified. After refinement of the conserved regions, based on its length, one conserved region is identified for which the primers and probes are reported for virus detection. The refined conserved regions are also used to identify T-cell and B-cell epitopes along with their immunogenic and antigenic scores. Such scores are used for selecting the most immunogenic and antigenic epitopes. By executing this pipeline, 40 unique signature SNPs are identified resulting in 23 non-synonymous signature SNPs which provide 28 amino acid changes in protein. On the other hand, 12 conserved regions are selected based on refinement criteria out of which one is selected as the potential target for virus detection. Additionally, 22 MHC-I and 21 MHC-II restricted T-cell epitopes with 10 unique HLA alleles each and 17 B-cell epitopes are obtained for 12 conserved regions. All the results are validated both quantitatively and qualitatively which show that from genetic variability to synthetic vaccine design, the proposed pipeline can be used effectively to combat SARS-CoV-2.
  • Phylogenetic analysis of 17271 Indian SARSCoV-2 genomes to identify temporal and spatial hotspot mutations

    Ghosh N., Nandi S., Saha I.

    Article, PLoS ONE, 2022, DOI Link

    View abstract ⏷

    The second wave of SARS-CoV-2 has hit India hard and though the vaccination drive has started, moderate number of COVID affected patients is still present in the country, thereby leading to the analysis of the evolving virus strains. In this regard, multiple sequence alignment of 17271 Indian SARS-CoV-2 sequences is performed using MAFFT followed by their phylogenetic analysis using Nextstrain. Subsequently, mutation points as SNPs are identified by Nextstrain. Thereafter, from the aligned sequences temporal and spatial analysis are carried out to identify top 10 hotspot mutations in the coding regions based on entropy. Finally, to judge the functional characteristics of all the non-synonymous hotspot mutations, their changes in proteins are evaluated as biological functions considering the sequences by using PolyPhen-2 while I-Mutant 2.0 evaluates their structural stability. For both temporal and spatial analysis, there are 21 non-synonymous hotspot mutations which are unstable and damaging.
  • A review on evolution of emerging SARS-CoV-2 variants based on spike glycoprotein

    Ghosh N., Nandi S., Saha I.

    Review, International Immunopharmacology, 2022, DOI Link

    View abstract ⏷

    Since the inception of SARS-CoV-2 in December 2019, many variants have emerged over time. Some of these variants have resulted in transmissibility changes of the virus and may also have impact on diagnosis, therapeutics and even vaccines, thereby raising particular concerns in the scientific community. The variants which have mutations in Spike glycoprotein are the primary focus as it is the main target for neutralising antibodies. SARS-CoV-2 is known to infect human through Spike glycoprotein and uses receptor-binding domain (RBD) to bind to the ACE2 receptor in human. Thus, it is of utmost importance to study these variants and their corresponding mutations. Such 12 different important variants identified so far are B.1.1.7 (Alpha), B.1.351 (Beta), B.1.525 (Eta), B.1.427/B.1.429 (Epsilon), B.1.526 (Iota), B.1.617.1 (Kappa), B.1.617.2 (Delta), C.37 (Lambda), P.1 (Gamma), P.2 (Zeta), P.3 (Theta) and the recently discovered B.1.1.529 (Omicron). These variants have 84 unique mutations in Spike glycoprotein. To analyse such mutations, multiple sequence alignment of 77681 SARS-CoV-2 genomes of 98 countries over the period from January 2020 to July 2021 is performed followed by phylogenetic analysis. Also, characteristics of new emerging variants are elaborately discussed. The individual evolution of these mutation points and the respective variants are visualised and their characteristics are also reported. Moreover, to judge the characteristics of the non-synonymous mutation points (substitutions), their biological functions are evaluated by PolyPhen-2 while protein structural stability is evaluated using I-Mutant 2.0.
  • Characterisation of SARS-CoV-2 clades based on signature SNPs unveils continuous evolution

    Ghosh N., Saha I., Nandi S., Sharma N.

    Article, Methods, 2022, DOI Link

    View abstract ⏷

    Since the emergence of SARS-CoV-2 in Wuhan, China more than a year ago, it has spread across the world in a very short span of time. Although, different forms of vaccines are being rolled out for vaccination programs around the globe, the mutation of the virus is still a cause of concern among the research communities. Hence, it is important to study the constantly evolving virus and its strains in order to provide a much more stable form of cure. This fact motivated us to conduct this research where we have initially carried out multiple sequence alignment of 15359 and 3033 global dataset without Indian and the dataset of exclusive Indian SARS-CoV-2 genomes respectively, using MAFFT. Subsequently, phylogenetic analyses are performed using Nextstrain to identify virus clades. Consequently, the virus strains are found to be distributed among 5 major clades or clusters viz. 19A, 19B, 20A, 20B and 20C. Thereafter, mutation points as SNPs are identified in each clade. Henceforth, from each clade top 10 signature SNPs are identified based on their frequency i.e. number of occurrences in the virus genome. As a result, 50 such signature SNPs are individually identified for global dataset without Indian and dataset of exclusive Indian SARS-CoV-2 genomes respectively. Out of each 50 signature SNPs, 39 and 41 unique SNPs are identified among which 25 non-synonymous signature SNPs (out of 39) resulted in 30 amino acid changes in protein while 27 changes in amino acid are identified from 22 non-synonymous signature SNPs (out of 41). These 30 and 27 amino acid changes for the non-synonymous signature SNPs are visualised in their respective protein structure as well. Finally, in order to judge the characteristics of the identified clades, the non-synonymous signature SNPs are considered to evaluate the changes in proteins as biological functions with the sequences using PROVEAN and PolyPhen-2 while I-Mutant 2.0 is used to evaluate their structural stability. As a consequence, for global dataset without Indian sequences, G251V in ORF3a in clade 19A, F308Y and G196V in NSP4 and ORF3a in 19B are the unique amino acid changes which are responsible for defining each clade as they are all deleterious and unstable. Such changes which are common for both global dataset without Indian and dataset of exclusive Indian sequences are R203M in Nucleocapsid for 20B, T85I and Q57H in NSP2 and ORF3a respectively for 20C while for exclusive Indian sequences such unique changes are A97V in RdRp, G339S and G339C in NSP2 in 19A and Q57H in ORF3a in 20A.
  • Hotspot Mutations in SARS-CoV-2

    Saha I., Ghosh N., Sharma N., Nandi S.

    Article, Frontiers in Genetics, 2021, DOI Link

    View abstract ⏷

    Since its emergence in Wuhan, China, severe acute respiratory syndrome coronavirus-2 (SARS-CoV-2) has spread very rapidly around the world, resulting in a global pandemic. Though the vaccination process has started, the number of COVID-affected patients is still quite large. Hence, an analysis of hotspot mutations of the different evolving virus strains needs to be carried out. In this regard, multiple sequence alignment of 71,038 SARS-CoV-2 genomes of 98 countries over the period from January 2020 to June 2021 is performed using MAFFT followed by phylogenetic analysis in order to visualize the virus evolution. These steps resulted in the identification of hotspot mutations as deletions and substitutions in the coding regions based on entropy greater than or equal to 0.3, leading to a total of 45 unique hotspot mutations. Moreover, 10,286 Indian sequences are considered from 71,038 global SARS-CoV-2 sequences as a demonstrative example that gives 52 unique hotspot mutations. Furthermore, the evolution of the hotspot mutations along with the mutations in variants of concern is visualized, and their characteristics are discussed as well. Also, for all the non-synonymous substitutions (missense mutations), the functional consequences of amino acid changes in the respective protein structures are calculated using PolyPhen-2 and I-Mutant 2.0. In addition to this, SSIPe is used to report the binding affinity between the receptor-binding domain of Spike protein and human ACE2 protein by considering L452R, T478K, E484Q, and N501Y hotspot mutations in that region.
  • Genome-wide analysis of 10664 SARS-CoV-2 genomes to identify virus strains in 73 countries based on single nucleotide polymorphism

    Ghosh N., Saha I., Sharma N., Nandi S., Plewczynski D.

    Article, Virus Research, 2021, DOI Link

    View abstract ⏷

    Since the onslaught of SARS-CoV-2, the research community has been searching for a vaccine to fight against this virus. However, during this period, the virus has mutated to adapt to the different environmental conditions in the world and made the task of vaccine design more challenging. In this situation, the identification of virus strains is very much timely and important task. We have performed genome-wide analysis of 10664 SARS-CoV-2 genomes of 73 countries to identify and prepare a Single Nucleotide Polymorphism (SNP) dataset of SARS-CoV-2. Thereafter, with the use of this SNP data, the advantage of hierarchical clustering is taken care of in such a way so that Average Linkage and Complete Linkage with Jaccard and Hamming distance functions are applied separately in order to identify the virus strains as clusters present in the SNP data. In this regard, the consensus of both the clustering results are also considered while Silhouette index is used as a cluster validity index to measure the goodness of the clusters as well to determine the number of clusters or virus strains. As a result, we have identified five major clusters or virus strains present worldwide. Apart from quantitative measures, these clusters are also visualized using Visual Assessment of Tendency (VAT) plot. The evolution of these clusters are also shown. Furthermore, top 10 signature SNPs are identified in each cluster and the non-synonymous signature SNPs are visualised in the respective protein structures. Also, the sequence and structural homology-based prediction along with the protein structural stability of these non-synonymous signature SNPs are reported in order to judge the characteristics of the identified clusters. As a consequence, T85I, Q57H and R203M in NSP2, ORF3a and Nucleocapsid respectively are found to be responsible for Cluster 1 as they are damaging and unstable non-synonymous signature SNPs. Similarly, F506L and S507C in Exon are responsible for both Clusters 3 and 4 while Clusters 2 and 5 do not exhibit such behaviour due to the absence of any non-synonymous signature SNPs. In addition to all these, the code, SNP dataset, 10664 labelled SARS-CoV-2 strains and additional results as supplementary are provided through our website for further use.
  • NIDF: An Ensemble-inspired Feature Learning Framework for Network Intrusion Detection

    Nandi S., Maity S., Das M.

    Conference paper, Proceedings of 2020 IEEE International Women in Engineering (WIE) Conference on Electrical and Computer Engineering, WIECON-ECE 2020, 2020, DOI Link

    View abstract ⏷

    In today's world growth of network-based applications increasing rapidly, to protect sensitive information from various threads and attackers an effective intrusion detection system needs to be developed. A network administrator completely depends on an efficient intrusion detection system that detects intrusion from the network. So to make our information safe and secure we need to detect the intrusion such that the hackers are prevented from the damage our information. The machine learning-based intrusion detection is one of the useful approaches to detect the intrusion present in the network. In this article, we have developed an ensemble-inspired feature learning environment for detecting intrusion in the network using several machine learning based classifiers. At first, we have identified the furthermost suitable features from the NSL KDD dataset using multiple feature selection methods like gain ratio, relief, and information gain strategies. After that, the top most relevant feature has selected by using our ensemble method from the combined pre-identified features set. The robustness of our model has been measured by applying k-fold cross-validation. The classification accuracy we have measured by applying several machine learning classifiers (J48, Decision Tree, and Random Forest). We have seen that the random forest classifier gives the best classification accuracy of 99.58%. Finally, we have analyzed that our ensemble method gives the best result compared with other feature selection methods by using same of classifiers.
  • Detection of DDoS Attack and Classification Using a Hybrid Approach

    Nandi S., Phadikar S., Majumder K.

    Conference paper, ISEA-ISAP 2020 - Proceedings of the 3rd ISEA International Conference on Security and Privacy 2020, 2020, DOI Link

    View abstract ⏷

    In the area of cloud security, detection of DDoS attack is a challenging task such that legitimate users use the cloud resources properly. So in this paper, detection and classification of the attacking packets and normal packets are done by using various machine learning classifiers. We have selected the most relevant features from NSL KDD dataset using five (Information gain, gain ratio, chi-squared, ReliefF, and symmetrical uncertainty) commonly used feature selection methods. Now from the entire selected feature set, the most important features are selected by applying our hybrid feature selection method. Since all the anomalous instances of the dataset do not belong to DDoS category so we have separated only the DDoS packets from the dataset using the selected features. Finally, the dataset has been prepared and named as KDD DDoS dataset by considering the selected DDoS packets and normal packets. This KDD DDoS dataset has been discretized using discretize tool in weka for getting better performance. Finally, this discretize dataset has been applied on some commonly used (Naive Bayes, Bayes Net, Decision Table, J48 and Random Forest) classifiers for determining the detection rate of the classifiers. 10 fold cross validation has been used here for measuring the robustness of the system. To measure the efficiency of our hybrid feature selection method, we have also applied the same set of classifiers on the NSL KDD dataset, where it gives the best anomaly detection rate of 99.72% and average detection rate 98.47% similarly, we have applied the same set of classifiers on NSL DDoS dataset and obtain the average DDoS detection of 99.01% and the best DDoS detection rate of 99.86%. In order to compare the performance of our proposed hybrid method, we have also applied the existing feature selection methods and measured the detection rate using the same set of classifiers. Finally, we have seen that our hybrid approach for detecting the DDoS attack gives the best detection rate compared to some existing methods.
  • Fractal image compression with quadtree partitioning and a new fast classification strategy

    Nandi U., Santra S., Mandal J.K., Nandi S.

    Conference paper, Proceedings of the 2015 3rd International Conference on Computer, Communication, Control and Information Technology, C3IT 2015, 2015, DOI Link

    View abstract ⏷

    In this paper, a new fast classification strategy is proposed for fractal image compression with quadtree partitioning technique. The scheme significantly reduces the number of mean square error (MSE) computations during encoding of images. Performance in terms of compression ratios, compression time and PSNR of the fractal image compression with existing and proposed classification strategy are compared. Both techniques use quadtree partitioning scheme. The proposed classification strategy reduces the compression time significantly of the fractal image compression technique maintaining compression ratio and PSNR almost same with its counterpart.

Patents

Projects

Scholars

Interests

  • Complex Network Analysis
  • Database Management Systems
  • Operating Systems
  • Social Network Analysis

Thought Leaderships

There are no Thought Leaderships associated with this faculty.

Top Achievements

Research Area

No research areas found for this faculty.

Computer Science and Engineering is a fast-evolving discipline and this is an exciting time to become a Computer Scientist!

Computer Science and Engineering is a fast-evolving discipline and this is an exciting time to become a Computer Scientist!

Recent Updates

No recent updates found.

Education
2014
B.Sc. in Computer Science
Vidyasagar University
2016
M.Sc. in Computer Science
Vidyasagar University
2019
M.Tech. in Computer Science and Engineering
Maulana Abul Kalam Azad University of Technology
2026
Ph.D. in Computer Science and Engineering
National Institute of Technology Durgapur
Experience
  • Served as a Junior Research Fellow (SERB-DST Funded Project) at the Department of Computer Science and Engineering, NITTTR Kolkata, conducting large-scale in silico analysis of COVID-19 genomic sequences.
Research Interests
  • Research interests include Complex Network Analysis, Social Network Analysis, Influential Spreader Identification, Influence Maximization, and Graph Representation Learning.
Awards & Fellowships
  • Selected for the Erasmus+ International Credit Mobility (ICM) Programme for collaborative research at the Polytechnic Institute of Castelo Branco, Portugal (March–June 2023).
  • Awarded the GATE Scholarship by the Ministry of Human Resource Development (MHRD), Government of India, during the M.Tech. programme (2017–2019).
Memberships
Publications
  • Community-based voting approach to enhance the spreading dynamics by identifying a group of influential spreaders in complex networks

    Nandi S., Curado Malta M., Maji G., Dutta A.

    Article, Journal of Computational Science, 2025, DOI Link

    View abstract ⏷

    Exploring a group of influential spreaders to acquire maximum influence has become an emerging area of research in complex network analysis. The main challenge of this research is to identify the group of important nodes that are scattered broadly, such that the propagation ability of information is maximum to a network. Researchers proposed many centrality-based approaches with certain limitations to identify the influential nodes (spreaders) considering different properties of the networks. To find a group of spreaders, the VoteRank (a voting mechanism) based method produces effective results with low time complexity, where in each iteration, the node votes for its neighbors by its voting capability, and the node obtaining the maximum vote score is identified as an influential spreader. The major loophole of existing VoteRank methods is measuring the voting capability based on the degree, k-shell index, or contribution of neighbors methods, which does not efficiently identify the spreaders from the diverse regions based on their spreading ability. In this paper, we propose a novel Community-based VoteRank method (CVoteRank) to identify a group of influential spreaders from diverse network regions by which the diffusion process is enhanced. Firstly, we measure every node's spreading ability based on intra- and inter-connectivity structure in a community, which signifies the local and global importance of the node. To identify the seed nodes, we assign the spreading ability to that node's voting capability and iteratively calculate the voting score of a node based on its neighboring voting capability and its spreading ability. Then, the node acquiring the maximum voting score is identified as the influential spreader in each iteration. Finally, to solve the problem of influence overlapping, CVoteRank reduces the voting capability of the neighboring nodes of the identified spreader. The efficiency of CVoteRank is evaluated and compared with the different state-of-the-art methods on twelve real networks. Utilizing the stochastic susceptible–infected–recovered epidemic method, we calculate the infected scale, final infected scale, and the average shortest path length among the identified spreaders. The experimental results show that CVoteRank identifies the most efficient spreaders with the highest spreading ability within a short period and the maximum reachability, and the identified spreaders are situated at diverse portions of the networks.
  • IC-SNI: measuring nodes’ influential capability in complex networks through structural and neighboring information

    Nandi S., CuradoMalta M., Maji G., Dutta A.

    Article, Knowledge and Information Systems, 2025, DOI Link

    View abstract ⏷

    Influential nodes are the important nodes that most efficiently control the propagation process throughout the network. Among various structural-based methods, degree centrality, k-shell decomposition, or their combination identify influential nodes with relatively low computational complexity, making them suitable for large-scale network analysis. However, these methods do not necessarily explore nodes’ underlying structure and neighboring information, which poses a significant challenge for researchers in developing timely and efficient heuristics considering appropriate network characteristics. In this study, we propose a new method (IC-SNI) to measure the influential capability of the nodes. IC-SNI minimizes the loopholes of the local and global centrality and calculates the topological positional structure by considering the local and global contribution of the neighbors. Exploring the path structural information, we introduce two new measurements (connectivity strength and effective distance) to capture the structural properties among the neighboring nodes. Finally, the influential capability of a node is calculated by aggregating the structural and neighboring information of up to two-hop neighboring nodes. Evaluated on nine benchmark datasets, IC-SNI demonstrates superior performance with the highest average ranking correlation of 0.813 with the SIR simulator and a 34.1% improvement comparing state-of-the-art methods in identifying influential spreaders. The results show that IC-SNI efficiently identifies the influential spreaders in diverse real networks by accurately integrating structural and neighboring information.
  • Exploring emerging spreaders through GCN-based link prediction and a novel centrality method

    Nandi S., Maji G., Dutta A.

    Conference paper, International Conference on Communication Systems and Networks, COMSNETS, 2025, DOI Link

    View abstract ⏷

    Exploring influential spreaders and predicting missing links in complex networks is essential for understanding and effectively controlling network dynamics. This paper presents a Graph Convolutional Network (GCN)-based link prediction method to estimate the probability of future link formation. We incorporate node features that capture local and global topological connectivity structures and feed these into the GCN model, where convolutional layers aggregate neighboring information and transform node features. This approach enables the model to capture structural patterns by integrating local and global information from neighboring nodes. In the final layer, the GCN model computes a prediction score representing the likelihood of an edge's existence, using insights gained during training. Finally, considering the predicted links, we update the network structure and introduce a novel centrality method called Emerging Spreader Centrality (ESC) to identify emerging spreaders within this augmented network. We conduct two separate experiments to evaluate the performance of the GCN-based link prediction and the ESC method, comparing their effectiveness with various state-of-the-art methods. Results demonstrate that our approach not only effectively predicts future links but also identifies emerging spreaders in the augmented networks.
  • Identifying vital spreaders in multiplex networks: measurement of layer dominance and a closeness-based layer gravity method

    Nandi S., Maji G., Dutta A.

    Article, Journal of Supercomputing, 2025, DOI Link

    View abstract ⏷

    The exploration of multiplex networks has become an emerging field of research due to the existence of different layers with diverse connectivity structures in almost every real network. Effectively managing a multiplex network is challenging, requiring the identification of vital spreaders (i.e., nodes) by measuring their importance. After reviewing the existing studies, it becomes clear that the dominance of individual layers has not been systematically evaluated in isolation in multiplex networks. In this study, we present a novel approach to measure the dominance of individual layers depending on two distinct parameters: node activeness and edge activeness. After that, we calculate the centrality value for each node on a per-layer basis and construct a centrality vector based on existing centrality methods and a novel Closeness-based Layer Gravity (CLG) method. Finally, the vital spreaders are identified by evaluating the importance of nodes through a mapping technique that aggregates the dominance of the layers with centrality values of the nodes from the respective layers. This proposed framework independently measures layer dominance and identifies vital spreaders, making it well suited for distributed and high-performance computing environments, and ensuring scalability across large multiplex networks. The performance of our proposed method is evaluated against the multiplex-based SIR epidemic simulator, and we observe that amalgamating our proposed layer dominance concept with the CLG method effectively identifies vital nodes, achieving a maximum average ranking similarity of 80.93% across various percentages of identified spreaders, considering eight real multiplex networks. By evaluating network robustness through the normalized LCC (Largest Connected Component) value after removing various percentages of identified spreaders, our method achieves the lowest average normalized LCC value of 0.751, outperforming state-of-the-art approaches.
  • Local Closeness Gravity Model to Identify the Vital Nodes in Complex Networks

    Nandi S., Dutta A.

    Conference paper, 2024 16th International Conference on COMmunication Systems and NETworkS, COMSNETS 2024, 2024, DOI Link

    View abstract ⏷

    In complex network analysis, identifying the viral nodes is a major concern of the research domain by which any kind of information or infection is controlled throughout the entire network. Several algorithms have been developed over the past few years to identify the viral nodes (influential spreaders) considering many properties of the network. Among them, some authors proposed gravity-based centrality to identify the vital nodes based on the law of gravity with certain limitations. The major limitation of existing gravity-based methods is the mass of the object (i.e. node) is considered as the degree or kshell index only, which does not always signify the spreading ability of the nodes. To address this research challenge, we propose an innovative Local Closeness Gravity method (named LCG) to measure the influential ability of individual nodes, facilitating the identification of the vital nodes in the network. To minimize the computational complexity of Closeness centrality, at first, we measure the local Closeness centrality of individual nodes considering all the nodes residing in the truncation radius. Thereafter we introduce a new parameter 'information sharing ability' based on connectivity strength to measure the distance between the nodes. Finally, the influential ability of each node is measured based on the gravity model considering the local closeness centrality, kshell index, and the distance. The efficiency of LCG is compared with the existing baseline centrality methods by using the Susceptible-Infectious-Recovered (SIR) simulator. The correlation between the LCG method and the baseline centrality methods with the SIR method is compared by Kendalls' tau method considering various infection probabilities and various percentages of seed nodes respectively. The ranking uniqueness of the LCG method and the baseline centrality methods are also measured by the monotonicity metrics. Through the obtained results and various analyses, it becomes evident that the LCG method adeptly discerns the vital nodes within the networks.
  • CCC: A Spreader Selection Approach to Control Spreading Dynamics in Complex Networks

    Nandi S., Mandal D., Dutta A.

    Conference paper, Proceedings - 2024 IEEE/WIC International Conference on Web Intelligence and Intelligent Agent Technology, WI-IAT 2024, 2024, DOI Link

    View abstract ⏷

    Due to the diverse structure and varying sizes of networks, identifying super spreaders to limit the spread of information (or infection) has become a significant research challenge. Community-based approaches have shown effectiveness in locating spreaders across diverse network positions. To address gaps in current methods, we propose Community-based Closeness Coreness (CCC), a novel approach for controlling spreading dynamics. CCC first identifies gateway nodes within each community and calculates each node's closeness with these gateway nodes within a truncation radius, reflecting its spreading efficiency. Node coreness is measured by combining the k-shell index and neighbor connectivity, and nodes are ranked based on their aggregated closeness and coreness. Finally, CCC selects spreaders from all communities according to node ranking and community size. Measuring the performance of CCC on six real networks shows that it outperforms baseline methods by identifying super spreaders that enable rapid and extensive diffusion.
  • Identification of Influential Spreaders in a Partially Changed Dynamic Network

    Sarkar M., Nandi S., Maji G., Dutta A.

    Conference paper, 2024 16th International Conference on COMmunication Systems and NETworkS, COMSNETS 2024, 2024, DOI Link

    View abstract ⏷

    Identification of influential spreaders plays a significant role in maximizing or controlling any spreading process in a network. Influential spreaders or influential nodes are the most important nodes in a network that play a key role in spreading information, ideas, or diseases. To identify and rank these important nodes many centrality measures have been proposed by several authors over the past few years. Identifying the major research gap, we observe measuring the node importance in dynamic networks is very limited. Dynamic networks are defined as those networks which change the connectivity structure of the network at every time interval, also known as a time-varying network, as the links are active only at certain points in time. In dynamic networks, ranking the nodes (or finding the most important nodes) becomes computation-heavy if we have to compute the centrality measures on every event (changes in the connectedness of the network). We have considered two easy-to-compute and well-established centrality metrics (K-shell and degree) and attempted to estimate the node ranking by approximating the centrality measures through partial computation for a network that has undergone some changes in the topology (the edge connectivity, some edges become dormant and some new connections between two nodes might have formed). Our primary objective is to avoid computing centrality measures every time, during the changes of connectivity change. We utilize the existing network measures and other parameters along with the changes of connectivity structure to arrive at the updated measures as well as ranking heuristically. It is expected that after every event the topology of the network changes, which in turn would change centrality measures. The focus of the present study is to find out without further re-computation from the beginning the changes in K-shell centrality and degree centrality measures on a particular network model after some changes occur. This proposed method will heuristically estimate the changed k shell values using partial computation.
  • IS-PEW: Identifying Influential Spreaders Using Potential Edge Weight in Complex Networks

    Nandi S., Malta M.C., Maji G., Dutta A.

    Conference paper, Studies in Computational Intelligence, 2024, DOI Link

    View abstract ⏷

    Identifying the influential spreaders in complex networks has emerged as an important research challenge to control the spread of (mis)information or infectious diseases. Researchers have proposed many centrality measures to identify the influential nodes (spreaders) in the past few years. Still, most of them have not considered the importance of the edges in unweighted networks. To address this issue, we propose a novel centrality measure to identify the spreading ability of the Influential Spreaders using the Potential Edge Weight method (IS-PEW). Considering the connectivity structure, the ability of information exchange, and the importance of neighbouring nodes, we measure the potential edge weight. The ranking similarity of spreaders identified by IS-PEW and the baseline centrality methods are compared with the Susceptible-Infectious-Recovered (SIR) epidemic simulator using Kendall’s rank correlation. The spreading ability of the top-ranking spreaders is also compared for five different percentages of top-ranking node sets using six different real networks.
  • Semi-Global Circular Centrality to find Influential Spreaders

    Bhuiya A., Chowdhury K., Nandi S., Dutta A.

    Conference paper, 2023 15th International Conference on COMmunication Systems and NETworkS, COMSNETS 2023, 2023, DOI Link

    View abstract ⏷

    Smartphone use and social network connectivity are becoming more popular. Information sharing is becoming easier and faster. Influential spreaders in social networks play an important role. The identification of these influential nodes becomes a critical issue in social network analysis. Centrality methods are used to identify the influential nodes. There are many centrality methods proposed by researchers. The centrality methods can be classified into mainly four types: local centrality method, global centrality method, semi-global centrality method, and hybrid centrality. However, we have observed that the semi-global centrality method is identifying the ranks of a node based on the few levels of connectivity of a node and has not taken so much time. We are now proposing a new node ranking method called the 'semi-global circular method.' This method finds the top influential spreaders in the dense part of the network. We have applied the susceptible-infected-recovered epidemic model to our toy network to examine the performance of the proposed method. The result shows us that the performance of the proposed method is good.
  • Bioinformatics pipeline unveils genetic variability to synthetic vaccine design for Indian SARS-CoV-2 genomes

    Ghosh N., Saha I., Sharma N., Nandi S.

    Article, International Immunopharmacology, 2022, DOI Link

    View abstract ⏷

    In the worrisome scenarios of various waves of SARS-CoV-2 pandemic, a comprehensive bioinformatics pipeline is essential to analyse the virus genomes in order to understand its evolution, thereby identifying mutations as signature SNPs, conserved regions and subsequently to design epitope based synthetic vaccine. We have thus performed multiple sequence alignment of 4996 Indian SARS-CoV-2 genomes as a case study using MAFFT followed by phylogenetic analysis using Nextstrain to identify virus clades. Furthermore, based on the entropy of each genomic coordinate of the aligned sequences, conserved regions are identified. After refinement of the conserved regions, based on its length, one conserved region is identified for which the primers and probes are reported for virus detection. The refined conserved regions are also used to identify T-cell and B-cell epitopes along with their immunogenic and antigenic scores. Such scores are used for selecting the most immunogenic and antigenic epitopes. By executing this pipeline, 40 unique signature SNPs are identified resulting in 23 non-synonymous signature SNPs which provide 28 amino acid changes in protein. On the other hand, 12 conserved regions are selected based on refinement criteria out of which one is selected as the potential target for virus detection. Additionally, 22 MHC-I and 21 MHC-II restricted T-cell epitopes with 10 unique HLA alleles each and 17 B-cell epitopes are obtained for 12 conserved regions. All the results are validated both quantitatively and qualitatively which show that from genetic variability to synthetic vaccine design, the proposed pipeline can be used effectively to combat SARS-CoV-2.
  • Phylogenetic analysis of 17271 Indian SARSCoV-2 genomes to identify temporal and spatial hotspot mutations

    Ghosh N., Nandi S., Saha I.

    Article, PLoS ONE, 2022, DOI Link

    View abstract ⏷

    The second wave of SARS-CoV-2 has hit India hard and though the vaccination drive has started, moderate number of COVID affected patients is still present in the country, thereby leading to the analysis of the evolving virus strains. In this regard, multiple sequence alignment of 17271 Indian SARS-CoV-2 sequences is performed using MAFFT followed by their phylogenetic analysis using Nextstrain. Subsequently, mutation points as SNPs are identified by Nextstrain. Thereafter, from the aligned sequences temporal and spatial analysis are carried out to identify top 10 hotspot mutations in the coding regions based on entropy. Finally, to judge the functional characteristics of all the non-synonymous hotspot mutations, their changes in proteins are evaluated as biological functions considering the sequences by using PolyPhen-2 while I-Mutant 2.0 evaluates their structural stability. For both temporal and spatial analysis, there are 21 non-synonymous hotspot mutations which are unstable and damaging.
  • A review on evolution of emerging SARS-CoV-2 variants based on spike glycoprotein

    Ghosh N., Nandi S., Saha I.

    Review, International Immunopharmacology, 2022, DOI Link

    View abstract ⏷

    Since the inception of SARS-CoV-2 in December 2019, many variants have emerged over time. Some of these variants have resulted in transmissibility changes of the virus and may also have impact on diagnosis, therapeutics and even vaccines, thereby raising particular concerns in the scientific community. The variants which have mutations in Spike glycoprotein are the primary focus as it is the main target for neutralising antibodies. SARS-CoV-2 is known to infect human through Spike glycoprotein and uses receptor-binding domain (RBD) to bind to the ACE2 receptor in human. Thus, it is of utmost importance to study these variants and their corresponding mutations. Such 12 different important variants identified so far are B.1.1.7 (Alpha), B.1.351 (Beta), B.1.525 (Eta), B.1.427/B.1.429 (Epsilon), B.1.526 (Iota), B.1.617.1 (Kappa), B.1.617.2 (Delta), C.37 (Lambda), P.1 (Gamma), P.2 (Zeta), P.3 (Theta) and the recently discovered B.1.1.529 (Omicron). These variants have 84 unique mutations in Spike glycoprotein. To analyse such mutations, multiple sequence alignment of 77681 SARS-CoV-2 genomes of 98 countries over the period from January 2020 to July 2021 is performed followed by phylogenetic analysis. Also, characteristics of new emerging variants are elaborately discussed. The individual evolution of these mutation points and the respective variants are visualised and their characteristics are also reported. Moreover, to judge the characteristics of the non-synonymous mutation points (substitutions), their biological functions are evaluated by PolyPhen-2 while protein structural stability is evaluated using I-Mutant 2.0.
  • Characterisation of SARS-CoV-2 clades based on signature SNPs unveils continuous evolution

    Ghosh N., Saha I., Nandi S., Sharma N.

    Article, Methods, 2022, DOI Link

    View abstract ⏷

    Since the emergence of SARS-CoV-2 in Wuhan, China more than a year ago, it has spread across the world in a very short span of time. Although, different forms of vaccines are being rolled out for vaccination programs around the globe, the mutation of the virus is still a cause of concern among the research communities. Hence, it is important to study the constantly evolving virus and its strains in order to provide a much more stable form of cure. This fact motivated us to conduct this research where we have initially carried out multiple sequence alignment of 15359 and 3033 global dataset without Indian and the dataset of exclusive Indian SARS-CoV-2 genomes respectively, using MAFFT. Subsequently, phylogenetic analyses are performed using Nextstrain to identify virus clades. Consequently, the virus strains are found to be distributed among 5 major clades or clusters viz. 19A, 19B, 20A, 20B and 20C. Thereafter, mutation points as SNPs are identified in each clade. Henceforth, from each clade top 10 signature SNPs are identified based on their frequency i.e. number of occurrences in the virus genome. As a result, 50 such signature SNPs are individually identified for global dataset without Indian and dataset of exclusive Indian SARS-CoV-2 genomes respectively. Out of each 50 signature SNPs, 39 and 41 unique SNPs are identified among which 25 non-synonymous signature SNPs (out of 39) resulted in 30 amino acid changes in protein while 27 changes in amino acid are identified from 22 non-synonymous signature SNPs (out of 41). These 30 and 27 amino acid changes for the non-synonymous signature SNPs are visualised in their respective protein structure as well. Finally, in order to judge the characteristics of the identified clades, the non-synonymous signature SNPs are considered to evaluate the changes in proteins as biological functions with the sequences using PROVEAN and PolyPhen-2 while I-Mutant 2.0 is used to evaluate their structural stability. As a consequence, for global dataset without Indian sequences, G251V in ORF3a in clade 19A, F308Y and G196V in NSP4 and ORF3a in 19B are the unique amino acid changes which are responsible for defining each clade as they are all deleterious and unstable. Such changes which are common for both global dataset without Indian and dataset of exclusive Indian sequences are R203M in Nucleocapsid for 20B, T85I and Q57H in NSP2 and ORF3a respectively for 20C while for exclusive Indian sequences such unique changes are A97V in RdRp, G339S and G339C in NSP2 in 19A and Q57H in ORF3a in 20A.
  • Hotspot Mutations in SARS-CoV-2

    Saha I., Ghosh N., Sharma N., Nandi S.

    Article, Frontiers in Genetics, 2021, DOI Link

    View abstract ⏷

    Since its emergence in Wuhan, China, severe acute respiratory syndrome coronavirus-2 (SARS-CoV-2) has spread very rapidly around the world, resulting in a global pandemic. Though the vaccination process has started, the number of COVID-affected patients is still quite large. Hence, an analysis of hotspot mutations of the different evolving virus strains needs to be carried out. In this regard, multiple sequence alignment of 71,038 SARS-CoV-2 genomes of 98 countries over the period from January 2020 to June 2021 is performed using MAFFT followed by phylogenetic analysis in order to visualize the virus evolution. These steps resulted in the identification of hotspot mutations as deletions and substitutions in the coding regions based on entropy greater than or equal to 0.3, leading to a total of 45 unique hotspot mutations. Moreover, 10,286 Indian sequences are considered from 71,038 global SARS-CoV-2 sequences as a demonstrative example that gives 52 unique hotspot mutations. Furthermore, the evolution of the hotspot mutations along with the mutations in variants of concern is visualized, and their characteristics are discussed as well. Also, for all the non-synonymous substitutions (missense mutations), the functional consequences of amino acid changes in the respective protein structures are calculated using PolyPhen-2 and I-Mutant 2.0. In addition to this, SSIPe is used to report the binding affinity between the receptor-binding domain of Spike protein and human ACE2 protein by considering L452R, T478K, E484Q, and N501Y hotspot mutations in that region.
  • Genome-wide analysis of 10664 SARS-CoV-2 genomes to identify virus strains in 73 countries based on single nucleotide polymorphism

    Ghosh N., Saha I., Sharma N., Nandi S., Plewczynski D.

    Article, Virus Research, 2021, DOI Link

    View abstract ⏷

    Since the onslaught of SARS-CoV-2, the research community has been searching for a vaccine to fight against this virus. However, during this period, the virus has mutated to adapt to the different environmental conditions in the world and made the task of vaccine design more challenging. In this situation, the identification of virus strains is very much timely and important task. We have performed genome-wide analysis of 10664 SARS-CoV-2 genomes of 73 countries to identify and prepare a Single Nucleotide Polymorphism (SNP) dataset of SARS-CoV-2. Thereafter, with the use of this SNP data, the advantage of hierarchical clustering is taken care of in such a way so that Average Linkage and Complete Linkage with Jaccard and Hamming distance functions are applied separately in order to identify the virus strains as clusters present in the SNP data. In this regard, the consensus of both the clustering results are also considered while Silhouette index is used as a cluster validity index to measure the goodness of the clusters as well to determine the number of clusters or virus strains. As a result, we have identified five major clusters or virus strains present worldwide. Apart from quantitative measures, these clusters are also visualized using Visual Assessment of Tendency (VAT) plot. The evolution of these clusters are also shown. Furthermore, top 10 signature SNPs are identified in each cluster and the non-synonymous signature SNPs are visualised in the respective protein structures. Also, the sequence and structural homology-based prediction along with the protein structural stability of these non-synonymous signature SNPs are reported in order to judge the characteristics of the identified clusters. As a consequence, T85I, Q57H and R203M in NSP2, ORF3a and Nucleocapsid respectively are found to be responsible for Cluster 1 as they are damaging and unstable non-synonymous signature SNPs. Similarly, F506L and S507C in Exon are responsible for both Clusters 3 and 4 while Clusters 2 and 5 do not exhibit such behaviour due to the absence of any non-synonymous signature SNPs. In addition to all these, the code, SNP dataset, 10664 labelled SARS-CoV-2 strains and additional results as supplementary are provided through our website for further use.
  • NIDF: An Ensemble-inspired Feature Learning Framework for Network Intrusion Detection

    Nandi S., Maity S., Das M.

    Conference paper, Proceedings of 2020 IEEE International Women in Engineering (WIE) Conference on Electrical and Computer Engineering, WIECON-ECE 2020, 2020, DOI Link

    View abstract ⏷

    In today's world growth of network-based applications increasing rapidly, to protect sensitive information from various threads and attackers an effective intrusion detection system needs to be developed. A network administrator completely depends on an efficient intrusion detection system that detects intrusion from the network. So to make our information safe and secure we need to detect the intrusion such that the hackers are prevented from the damage our information. The machine learning-based intrusion detection is one of the useful approaches to detect the intrusion present in the network. In this article, we have developed an ensemble-inspired feature learning environment for detecting intrusion in the network using several machine learning based classifiers. At first, we have identified the furthermost suitable features from the NSL KDD dataset using multiple feature selection methods like gain ratio, relief, and information gain strategies. After that, the top most relevant feature has selected by using our ensemble method from the combined pre-identified features set. The robustness of our model has been measured by applying k-fold cross-validation. The classification accuracy we have measured by applying several machine learning classifiers (J48, Decision Tree, and Random Forest). We have seen that the random forest classifier gives the best classification accuracy of 99.58%. Finally, we have analyzed that our ensemble method gives the best result compared with other feature selection methods by using same of classifiers.
  • Detection of DDoS Attack and Classification Using a Hybrid Approach

    Nandi S., Phadikar S., Majumder K.

    Conference paper, ISEA-ISAP 2020 - Proceedings of the 3rd ISEA International Conference on Security and Privacy 2020, 2020, DOI Link

    View abstract ⏷

    In the area of cloud security, detection of DDoS attack is a challenging task such that legitimate users use the cloud resources properly. So in this paper, detection and classification of the attacking packets and normal packets are done by using various machine learning classifiers. We have selected the most relevant features from NSL KDD dataset using five (Information gain, gain ratio, chi-squared, ReliefF, and symmetrical uncertainty) commonly used feature selection methods. Now from the entire selected feature set, the most important features are selected by applying our hybrid feature selection method. Since all the anomalous instances of the dataset do not belong to DDoS category so we have separated only the DDoS packets from the dataset using the selected features. Finally, the dataset has been prepared and named as KDD DDoS dataset by considering the selected DDoS packets and normal packets. This KDD DDoS dataset has been discretized using discretize tool in weka for getting better performance. Finally, this discretize dataset has been applied on some commonly used (Naive Bayes, Bayes Net, Decision Table, J48 and Random Forest) classifiers for determining the detection rate of the classifiers. 10 fold cross validation has been used here for measuring the robustness of the system. To measure the efficiency of our hybrid feature selection method, we have also applied the same set of classifiers on the NSL KDD dataset, where it gives the best anomaly detection rate of 99.72% and average detection rate 98.47% similarly, we have applied the same set of classifiers on NSL DDoS dataset and obtain the average DDoS detection of 99.01% and the best DDoS detection rate of 99.86%. In order to compare the performance of our proposed hybrid method, we have also applied the existing feature selection methods and measured the detection rate using the same set of classifiers. Finally, we have seen that our hybrid approach for detecting the DDoS attack gives the best detection rate compared to some existing methods.
  • Fractal image compression with quadtree partitioning and a new fast classification strategy

    Nandi U., Santra S., Mandal J.K., Nandi S.

    Conference paper, Proceedings of the 2015 3rd International Conference on Computer, Communication, Control and Information Technology, C3IT 2015, 2015, DOI Link

    View abstract ⏷

    In this paper, a new fast classification strategy is proposed for fractal image compression with quadtree partitioning technique. The scheme significantly reduces the number of mean square error (MSE) computations during encoding of images. Performance in terms of compression ratios, compression time and PSNR of the fractal image compression with existing and proposed classification strategy are compared. Both techniques use quadtree partitioning scheme. The proposed classification strategy reduces the compression time significantly of the fractal image compression technique maintaining compression ratio and PSNR almost same with its counterpart.
Contact Details

suman.n@srmap.edu.in

Scholars
Interests

  • Complex Network Analysis
  • Database Management Systems
  • Operating Systems
  • Social Network Analysis

Education
2014
B.Sc. in Computer Science
Vidyasagar University
2016
M.Sc. in Computer Science
Vidyasagar University
2019
M.Tech. in Computer Science and Engineering
Maulana Abul Kalam Azad University of Technology
2026
Ph.D. in Computer Science and Engineering
National Institute of Technology Durgapur
Experience
  • Served as a Junior Research Fellow (SERB-DST Funded Project) at the Department of Computer Science and Engineering, NITTTR Kolkata, conducting large-scale in silico analysis of COVID-19 genomic sequences.
Research Interests
  • Research interests include Complex Network Analysis, Social Network Analysis, Influential Spreader Identification, Influence Maximization, and Graph Representation Learning.
Awards & Fellowships
  • Selected for the Erasmus+ International Credit Mobility (ICM) Programme for collaborative research at the Polytechnic Institute of Castelo Branco, Portugal (March–June 2023).
  • Awarded the GATE Scholarship by the Ministry of Human Resource Development (MHRD), Government of India, during the M.Tech. programme (2017–2019).
Memberships
Publications
  • Community-based voting approach to enhance the spreading dynamics by identifying a group of influential spreaders in complex networks

    Nandi S., Curado Malta M., Maji G., Dutta A.

    Article, Journal of Computational Science, 2025, DOI Link

    View abstract ⏷

    Exploring a group of influential spreaders to acquire maximum influence has become an emerging area of research in complex network analysis. The main challenge of this research is to identify the group of important nodes that are scattered broadly, such that the propagation ability of information is maximum to a network. Researchers proposed many centrality-based approaches with certain limitations to identify the influential nodes (spreaders) considering different properties of the networks. To find a group of spreaders, the VoteRank (a voting mechanism) based method produces effective results with low time complexity, where in each iteration, the node votes for its neighbors by its voting capability, and the node obtaining the maximum vote score is identified as an influential spreader. The major loophole of existing VoteRank methods is measuring the voting capability based on the degree, k-shell index, or contribution of neighbors methods, which does not efficiently identify the spreaders from the diverse regions based on their spreading ability. In this paper, we propose a novel Community-based VoteRank method (CVoteRank) to identify a group of influential spreaders from diverse network regions by which the diffusion process is enhanced. Firstly, we measure every node's spreading ability based on intra- and inter-connectivity structure in a community, which signifies the local and global importance of the node. To identify the seed nodes, we assign the spreading ability to that node's voting capability and iteratively calculate the voting score of a node based on its neighboring voting capability and its spreading ability. Then, the node acquiring the maximum voting score is identified as the influential spreader in each iteration. Finally, to solve the problem of influence overlapping, CVoteRank reduces the voting capability of the neighboring nodes of the identified spreader. The efficiency of CVoteRank is evaluated and compared with the different state-of-the-art methods on twelve real networks. Utilizing the stochastic susceptible–infected–recovered epidemic method, we calculate the infected scale, final infected scale, and the average shortest path length among the identified spreaders. The experimental results show that CVoteRank identifies the most efficient spreaders with the highest spreading ability within a short period and the maximum reachability, and the identified spreaders are situated at diverse portions of the networks.
  • IC-SNI: measuring nodes’ influential capability in complex networks through structural and neighboring information

    Nandi S., CuradoMalta M., Maji G., Dutta A.

    Article, Knowledge and Information Systems, 2025, DOI Link

    View abstract ⏷

    Influential nodes are the important nodes that most efficiently control the propagation process throughout the network. Among various structural-based methods, degree centrality, k-shell decomposition, or their combination identify influential nodes with relatively low computational complexity, making them suitable for large-scale network analysis. However, these methods do not necessarily explore nodes’ underlying structure and neighboring information, which poses a significant challenge for researchers in developing timely and efficient heuristics considering appropriate network characteristics. In this study, we propose a new method (IC-SNI) to measure the influential capability of the nodes. IC-SNI minimizes the loopholes of the local and global centrality and calculates the topological positional structure by considering the local and global contribution of the neighbors. Exploring the path structural information, we introduce two new measurements (connectivity strength and effective distance) to capture the structural properties among the neighboring nodes. Finally, the influential capability of a node is calculated by aggregating the structural and neighboring information of up to two-hop neighboring nodes. Evaluated on nine benchmark datasets, IC-SNI demonstrates superior performance with the highest average ranking correlation of 0.813 with the SIR simulator and a 34.1% improvement comparing state-of-the-art methods in identifying influential spreaders. The results show that IC-SNI efficiently identifies the influential spreaders in diverse real networks by accurately integrating structural and neighboring information.
  • Exploring emerging spreaders through GCN-based link prediction and a novel centrality method

    Nandi S., Maji G., Dutta A.

    Conference paper, International Conference on Communication Systems and Networks, COMSNETS, 2025, DOI Link

    View abstract ⏷

    Exploring influential spreaders and predicting missing links in complex networks is essential for understanding and effectively controlling network dynamics. This paper presents a Graph Convolutional Network (GCN)-based link prediction method to estimate the probability of future link formation. We incorporate node features that capture local and global topological connectivity structures and feed these into the GCN model, where convolutional layers aggregate neighboring information and transform node features. This approach enables the model to capture structural patterns by integrating local and global information from neighboring nodes. In the final layer, the GCN model computes a prediction score representing the likelihood of an edge's existence, using insights gained during training. Finally, considering the predicted links, we update the network structure and introduce a novel centrality method called Emerging Spreader Centrality (ESC) to identify emerging spreaders within this augmented network. We conduct two separate experiments to evaluate the performance of the GCN-based link prediction and the ESC method, comparing their effectiveness with various state-of-the-art methods. Results demonstrate that our approach not only effectively predicts future links but also identifies emerging spreaders in the augmented networks.
  • Identifying vital spreaders in multiplex networks: measurement of layer dominance and a closeness-based layer gravity method

    Nandi S., Maji G., Dutta A.

    Article, Journal of Supercomputing, 2025, DOI Link

    View abstract ⏷

    The exploration of multiplex networks has become an emerging field of research due to the existence of different layers with diverse connectivity structures in almost every real network. Effectively managing a multiplex network is challenging, requiring the identification of vital spreaders (i.e., nodes) by measuring their importance. After reviewing the existing studies, it becomes clear that the dominance of individual layers has not been systematically evaluated in isolation in multiplex networks. In this study, we present a novel approach to measure the dominance of individual layers depending on two distinct parameters: node activeness and edge activeness. After that, we calculate the centrality value for each node on a per-layer basis and construct a centrality vector based on existing centrality methods and a novel Closeness-based Layer Gravity (CLG) method. Finally, the vital spreaders are identified by evaluating the importance of nodes through a mapping technique that aggregates the dominance of the layers with centrality values of the nodes from the respective layers. This proposed framework independently measures layer dominance and identifies vital spreaders, making it well suited for distributed and high-performance computing environments, and ensuring scalability across large multiplex networks. The performance of our proposed method is evaluated against the multiplex-based SIR epidemic simulator, and we observe that amalgamating our proposed layer dominance concept with the CLG method effectively identifies vital nodes, achieving a maximum average ranking similarity of 80.93% across various percentages of identified spreaders, considering eight real multiplex networks. By evaluating network robustness through the normalized LCC (Largest Connected Component) value after removing various percentages of identified spreaders, our method achieves the lowest average normalized LCC value of 0.751, outperforming state-of-the-art approaches.
  • Local Closeness Gravity Model to Identify the Vital Nodes in Complex Networks

    Nandi S., Dutta A.

    Conference paper, 2024 16th International Conference on COMmunication Systems and NETworkS, COMSNETS 2024, 2024, DOI Link

    View abstract ⏷

    In complex network analysis, identifying the viral nodes is a major concern of the research domain by which any kind of information or infection is controlled throughout the entire network. Several algorithms have been developed over the past few years to identify the viral nodes (influential spreaders) considering many properties of the network. Among them, some authors proposed gravity-based centrality to identify the vital nodes based on the law of gravity with certain limitations. The major limitation of existing gravity-based methods is the mass of the object (i.e. node) is considered as the degree or kshell index only, which does not always signify the spreading ability of the nodes. To address this research challenge, we propose an innovative Local Closeness Gravity method (named LCG) to measure the influential ability of individual nodes, facilitating the identification of the vital nodes in the network. To minimize the computational complexity of Closeness centrality, at first, we measure the local Closeness centrality of individual nodes considering all the nodes residing in the truncation radius. Thereafter we introduce a new parameter 'information sharing ability' based on connectivity strength to measure the distance between the nodes. Finally, the influential ability of each node is measured based on the gravity model considering the local closeness centrality, kshell index, and the distance. The efficiency of LCG is compared with the existing baseline centrality methods by using the Susceptible-Infectious-Recovered (SIR) simulator. The correlation between the LCG method and the baseline centrality methods with the SIR method is compared by Kendalls' tau method considering various infection probabilities and various percentages of seed nodes respectively. The ranking uniqueness of the LCG method and the baseline centrality methods are also measured by the monotonicity metrics. Through the obtained results and various analyses, it becomes evident that the LCG method adeptly discerns the vital nodes within the networks.
  • CCC: A Spreader Selection Approach to Control Spreading Dynamics in Complex Networks

    Nandi S., Mandal D., Dutta A.

    Conference paper, Proceedings - 2024 IEEE/WIC International Conference on Web Intelligence and Intelligent Agent Technology, WI-IAT 2024, 2024, DOI Link

    View abstract ⏷

    Due to the diverse structure and varying sizes of networks, identifying super spreaders to limit the spread of information (or infection) has become a significant research challenge. Community-based approaches have shown effectiveness in locating spreaders across diverse network positions. To address gaps in current methods, we propose Community-based Closeness Coreness (CCC), a novel approach for controlling spreading dynamics. CCC first identifies gateway nodes within each community and calculates each node's closeness with these gateway nodes within a truncation radius, reflecting its spreading efficiency. Node coreness is measured by combining the k-shell index and neighbor connectivity, and nodes are ranked based on their aggregated closeness and coreness. Finally, CCC selects spreaders from all communities according to node ranking and community size. Measuring the performance of CCC on six real networks shows that it outperforms baseline methods by identifying super spreaders that enable rapid and extensive diffusion.
  • Identification of Influential Spreaders in a Partially Changed Dynamic Network

    Sarkar M., Nandi S., Maji G., Dutta A.

    Conference paper, 2024 16th International Conference on COMmunication Systems and NETworkS, COMSNETS 2024, 2024, DOI Link

    View abstract ⏷

    Identification of influential spreaders plays a significant role in maximizing or controlling any spreading process in a network. Influential spreaders or influential nodes are the most important nodes in a network that play a key role in spreading information, ideas, or diseases. To identify and rank these important nodes many centrality measures have been proposed by several authors over the past few years. Identifying the major research gap, we observe measuring the node importance in dynamic networks is very limited. Dynamic networks are defined as those networks which change the connectivity structure of the network at every time interval, also known as a time-varying network, as the links are active only at certain points in time. In dynamic networks, ranking the nodes (or finding the most important nodes) becomes computation-heavy if we have to compute the centrality measures on every event (changes in the connectedness of the network). We have considered two easy-to-compute and well-established centrality metrics (K-shell and degree) and attempted to estimate the node ranking by approximating the centrality measures through partial computation for a network that has undergone some changes in the topology (the edge connectivity, some edges become dormant and some new connections between two nodes might have formed). Our primary objective is to avoid computing centrality measures every time, during the changes of connectivity change. We utilize the existing network measures and other parameters along with the changes of connectivity structure to arrive at the updated measures as well as ranking heuristically. It is expected that after every event the topology of the network changes, which in turn would change centrality measures. The focus of the present study is to find out without further re-computation from the beginning the changes in K-shell centrality and degree centrality measures on a particular network model after some changes occur. This proposed method will heuristically estimate the changed k shell values using partial computation.
  • IS-PEW: Identifying Influential Spreaders Using Potential Edge Weight in Complex Networks

    Nandi S., Malta M.C., Maji G., Dutta A.

    Conference paper, Studies in Computational Intelligence, 2024, DOI Link

    View abstract ⏷

    Identifying the influential spreaders in complex networks has emerged as an important research challenge to control the spread of (mis)information or infectious diseases. Researchers have proposed many centrality measures to identify the influential nodes (spreaders) in the past few years. Still, most of them have not considered the importance of the edges in unweighted networks. To address this issue, we propose a novel centrality measure to identify the spreading ability of the Influential Spreaders using the Potential Edge Weight method (IS-PEW). Considering the connectivity structure, the ability of information exchange, and the importance of neighbouring nodes, we measure the potential edge weight. The ranking similarity of spreaders identified by IS-PEW and the baseline centrality methods are compared with the Susceptible-Infectious-Recovered (SIR) epidemic simulator using Kendall’s rank correlation. The spreading ability of the top-ranking spreaders is also compared for five different percentages of top-ranking node sets using six different real networks.
  • Semi-Global Circular Centrality to find Influential Spreaders

    Bhuiya A., Chowdhury K., Nandi S., Dutta A.

    Conference paper, 2023 15th International Conference on COMmunication Systems and NETworkS, COMSNETS 2023, 2023, DOI Link

    View abstract ⏷

    Smartphone use and social network connectivity are becoming more popular. Information sharing is becoming easier and faster. Influential spreaders in social networks play an important role. The identification of these influential nodes becomes a critical issue in social network analysis. Centrality methods are used to identify the influential nodes. There are many centrality methods proposed by researchers. The centrality methods can be classified into mainly four types: local centrality method, global centrality method, semi-global centrality method, and hybrid centrality. However, we have observed that the semi-global centrality method is identifying the ranks of a node based on the few levels of connectivity of a node and has not taken so much time. We are now proposing a new node ranking method called the 'semi-global circular method.' This method finds the top influential spreaders in the dense part of the network. We have applied the susceptible-infected-recovered epidemic model to our toy network to examine the performance of the proposed method. The result shows us that the performance of the proposed method is good.
  • Bioinformatics pipeline unveils genetic variability to synthetic vaccine design for Indian SARS-CoV-2 genomes

    Ghosh N., Saha I., Sharma N., Nandi S.

    Article, International Immunopharmacology, 2022, DOI Link

    View abstract ⏷

    In the worrisome scenarios of various waves of SARS-CoV-2 pandemic, a comprehensive bioinformatics pipeline is essential to analyse the virus genomes in order to understand its evolution, thereby identifying mutations as signature SNPs, conserved regions and subsequently to design epitope based synthetic vaccine. We have thus performed multiple sequence alignment of 4996 Indian SARS-CoV-2 genomes as a case study using MAFFT followed by phylogenetic analysis using Nextstrain to identify virus clades. Furthermore, based on the entropy of each genomic coordinate of the aligned sequences, conserved regions are identified. After refinement of the conserved regions, based on its length, one conserved region is identified for which the primers and probes are reported for virus detection. The refined conserved regions are also used to identify T-cell and B-cell epitopes along with their immunogenic and antigenic scores. Such scores are used for selecting the most immunogenic and antigenic epitopes. By executing this pipeline, 40 unique signature SNPs are identified resulting in 23 non-synonymous signature SNPs which provide 28 amino acid changes in protein. On the other hand, 12 conserved regions are selected based on refinement criteria out of which one is selected as the potential target for virus detection. Additionally, 22 MHC-I and 21 MHC-II restricted T-cell epitopes with 10 unique HLA alleles each and 17 B-cell epitopes are obtained for 12 conserved regions. All the results are validated both quantitatively and qualitatively which show that from genetic variability to synthetic vaccine design, the proposed pipeline can be used effectively to combat SARS-CoV-2.
  • Phylogenetic analysis of 17271 Indian SARSCoV-2 genomes to identify temporal and spatial hotspot mutations

    Ghosh N., Nandi S., Saha I.

    Article, PLoS ONE, 2022, DOI Link

    View abstract ⏷

    The second wave of SARS-CoV-2 has hit India hard and though the vaccination drive has started, moderate number of COVID affected patients is still present in the country, thereby leading to the analysis of the evolving virus strains. In this regard, multiple sequence alignment of 17271 Indian SARS-CoV-2 sequences is performed using MAFFT followed by their phylogenetic analysis using Nextstrain. Subsequently, mutation points as SNPs are identified by Nextstrain. Thereafter, from the aligned sequences temporal and spatial analysis are carried out to identify top 10 hotspot mutations in the coding regions based on entropy. Finally, to judge the functional characteristics of all the non-synonymous hotspot mutations, their changes in proteins are evaluated as biological functions considering the sequences by using PolyPhen-2 while I-Mutant 2.0 evaluates their structural stability. For both temporal and spatial analysis, there are 21 non-synonymous hotspot mutations which are unstable and damaging.
  • A review on evolution of emerging SARS-CoV-2 variants based on spike glycoprotein

    Ghosh N., Nandi S., Saha I.

    Review, International Immunopharmacology, 2022, DOI Link

    View abstract ⏷

    Since the inception of SARS-CoV-2 in December 2019, many variants have emerged over time. Some of these variants have resulted in transmissibility changes of the virus and may also have impact on diagnosis, therapeutics and even vaccines, thereby raising particular concerns in the scientific community. The variants which have mutations in Spike glycoprotein are the primary focus as it is the main target for neutralising antibodies. SARS-CoV-2 is known to infect human through Spike glycoprotein and uses receptor-binding domain (RBD) to bind to the ACE2 receptor in human. Thus, it is of utmost importance to study these variants and their corresponding mutations. Such 12 different important variants identified so far are B.1.1.7 (Alpha), B.1.351 (Beta), B.1.525 (Eta), B.1.427/B.1.429 (Epsilon), B.1.526 (Iota), B.1.617.1 (Kappa), B.1.617.2 (Delta), C.37 (Lambda), P.1 (Gamma), P.2 (Zeta), P.3 (Theta) and the recently discovered B.1.1.529 (Omicron). These variants have 84 unique mutations in Spike glycoprotein. To analyse such mutations, multiple sequence alignment of 77681 SARS-CoV-2 genomes of 98 countries over the period from January 2020 to July 2021 is performed followed by phylogenetic analysis. Also, characteristics of new emerging variants are elaborately discussed. The individual evolution of these mutation points and the respective variants are visualised and their characteristics are also reported. Moreover, to judge the characteristics of the non-synonymous mutation points (substitutions), their biological functions are evaluated by PolyPhen-2 while protein structural stability is evaluated using I-Mutant 2.0.
  • Characterisation of SARS-CoV-2 clades based on signature SNPs unveils continuous evolution

    Ghosh N., Saha I., Nandi S., Sharma N.

    Article, Methods, 2022, DOI Link

    View abstract ⏷

    Since the emergence of SARS-CoV-2 in Wuhan, China more than a year ago, it has spread across the world in a very short span of time. Although, different forms of vaccines are being rolled out for vaccination programs around the globe, the mutation of the virus is still a cause of concern among the research communities. Hence, it is important to study the constantly evolving virus and its strains in order to provide a much more stable form of cure. This fact motivated us to conduct this research where we have initially carried out multiple sequence alignment of 15359 and 3033 global dataset without Indian and the dataset of exclusive Indian SARS-CoV-2 genomes respectively, using MAFFT. Subsequently, phylogenetic analyses are performed using Nextstrain to identify virus clades. Consequently, the virus strains are found to be distributed among 5 major clades or clusters viz. 19A, 19B, 20A, 20B and 20C. Thereafter, mutation points as SNPs are identified in each clade. Henceforth, from each clade top 10 signature SNPs are identified based on their frequency i.e. number of occurrences in the virus genome. As a result, 50 such signature SNPs are individually identified for global dataset without Indian and dataset of exclusive Indian SARS-CoV-2 genomes respectively. Out of each 50 signature SNPs, 39 and 41 unique SNPs are identified among which 25 non-synonymous signature SNPs (out of 39) resulted in 30 amino acid changes in protein while 27 changes in amino acid are identified from 22 non-synonymous signature SNPs (out of 41). These 30 and 27 amino acid changes for the non-synonymous signature SNPs are visualised in their respective protein structure as well. Finally, in order to judge the characteristics of the identified clades, the non-synonymous signature SNPs are considered to evaluate the changes in proteins as biological functions with the sequences using PROVEAN and PolyPhen-2 while I-Mutant 2.0 is used to evaluate their structural stability. As a consequence, for global dataset without Indian sequences, G251V in ORF3a in clade 19A, F308Y and G196V in NSP4 and ORF3a in 19B are the unique amino acid changes which are responsible for defining each clade as they are all deleterious and unstable. Such changes which are common for both global dataset without Indian and dataset of exclusive Indian sequences are R203M in Nucleocapsid for 20B, T85I and Q57H in NSP2 and ORF3a respectively for 20C while for exclusive Indian sequences such unique changes are A97V in RdRp, G339S and G339C in NSP2 in 19A and Q57H in ORF3a in 20A.
  • Hotspot Mutations in SARS-CoV-2

    Saha I., Ghosh N., Sharma N., Nandi S.

    Article, Frontiers in Genetics, 2021, DOI Link

    View abstract ⏷

    Since its emergence in Wuhan, China, severe acute respiratory syndrome coronavirus-2 (SARS-CoV-2) has spread very rapidly around the world, resulting in a global pandemic. Though the vaccination process has started, the number of COVID-affected patients is still quite large. Hence, an analysis of hotspot mutations of the different evolving virus strains needs to be carried out. In this regard, multiple sequence alignment of 71,038 SARS-CoV-2 genomes of 98 countries over the period from January 2020 to June 2021 is performed using MAFFT followed by phylogenetic analysis in order to visualize the virus evolution. These steps resulted in the identification of hotspot mutations as deletions and substitutions in the coding regions based on entropy greater than or equal to 0.3, leading to a total of 45 unique hotspot mutations. Moreover, 10,286 Indian sequences are considered from 71,038 global SARS-CoV-2 sequences as a demonstrative example that gives 52 unique hotspot mutations. Furthermore, the evolution of the hotspot mutations along with the mutations in variants of concern is visualized, and their characteristics are discussed as well. Also, for all the non-synonymous substitutions (missense mutations), the functional consequences of amino acid changes in the respective protein structures are calculated using PolyPhen-2 and I-Mutant 2.0. In addition to this, SSIPe is used to report the binding affinity between the receptor-binding domain of Spike protein and human ACE2 protein by considering L452R, T478K, E484Q, and N501Y hotspot mutations in that region.
  • Genome-wide analysis of 10664 SARS-CoV-2 genomes to identify virus strains in 73 countries based on single nucleotide polymorphism

    Ghosh N., Saha I., Sharma N., Nandi S., Plewczynski D.

    Article, Virus Research, 2021, DOI Link

    View abstract ⏷

    Since the onslaught of SARS-CoV-2, the research community has been searching for a vaccine to fight against this virus. However, during this period, the virus has mutated to adapt to the different environmental conditions in the world and made the task of vaccine design more challenging. In this situation, the identification of virus strains is very much timely and important task. We have performed genome-wide analysis of 10664 SARS-CoV-2 genomes of 73 countries to identify and prepare a Single Nucleotide Polymorphism (SNP) dataset of SARS-CoV-2. Thereafter, with the use of this SNP data, the advantage of hierarchical clustering is taken care of in such a way so that Average Linkage and Complete Linkage with Jaccard and Hamming distance functions are applied separately in order to identify the virus strains as clusters present in the SNP data. In this regard, the consensus of both the clustering results are also considered while Silhouette index is used as a cluster validity index to measure the goodness of the clusters as well to determine the number of clusters or virus strains. As a result, we have identified five major clusters or virus strains present worldwide. Apart from quantitative measures, these clusters are also visualized using Visual Assessment of Tendency (VAT) plot. The evolution of these clusters are also shown. Furthermore, top 10 signature SNPs are identified in each cluster and the non-synonymous signature SNPs are visualised in the respective protein structures. Also, the sequence and structural homology-based prediction along with the protein structural stability of these non-synonymous signature SNPs are reported in order to judge the characteristics of the identified clusters. As a consequence, T85I, Q57H and R203M in NSP2, ORF3a and Nucleocapsid respectively are found to be responsible for Cluster 1 as they are damaging and unstable non-synonymous signature SNPs. Similarly, F506L and S507C in Exon are responsible for both Clusters 3 and 4 while Clusters 2 and 5 do not exhibit such behaviour due to the absence of any non-synonymous signature SNPs. In addition to all these, the code, SNP dataset, 10664 labelled SARS-CoV-2 strains and additional results as supplementary are provided through our website for further use.
  • NIDF: An Ensemble-inspired Feature Learning Framework for Network Intrusion Detection

    Nandi S., Maity S., Das M.

    Conference paper, Proceedings of 2020 IEEE International Women in Engineering (WIE) Conference on Electrical and Computer Engineering, WIECON-ECE 2020, 2020, DOI Link

    View abstract ⏷

    In today's world growth of network-based applications increasing rapidly, to protect sensitive information from various threads and attackers an effective intrusion detection system needs to be developed. A network administrator completely depends on an efficient intrusion detection system that detects intrusion from the network. So to make our information safe and secure we need to detect the intrusion such that the hackers are prevented from the damage our information. The machine learning-based intrusion detection is one of the useful approaches to detect the intrusion present in the network. In this article, we have developed an ensemble-inspired feature learning environment for detecting intrusion in the network using several machine learning based classifiers. At first, we have identified the furthermost suitable features from the NSL KDD dataset using multiple feature selection methods like gain ratio, relief, and information gain strategies. After that, the top most relevant feature has selected by using our ensemble method from the combined pre-identified features set. The robustness of our model has been measured by applying k-fold cross-validation. The classification accuracy we have measured by applying several machine learning classifiers (J48, Decision Tree, and Random Forest). We have seen that the random forest classifier gives the best classification accuracy of 99.58%. Finally, we have analyzed that our ensemble method gives the best result compared with other feature selection methods by using same of classifiers.
  • Detection of DDoS Attack and Classification Using a Hybrid Approach

    Nandi S., Phadikar S., Majumder K.

    Conference paper, ISEA-ISAP 2020 - Proceedings of the 3rd ISEA International Conference on Security and Privacy 2020, 2020, DOI Link

    View abstract ⏷

    In the area of cloud security, detection of DDoS attack is a challenging task such that legitimate users use the cloud resources properly. So in this paper, detection and classification of the attacking packets and normal packets are done by using various machine learning classifiers. We have selected the most relevant features from NSL KDD dataset using five (Information gain, gain ratio, chi-squared, ReliefF, and symmetrical uncertainty) commonly used feature selection methods. Now from the entire selected feature set, the most important features are selected by applying our hybrid feature selection method. Since all the anomalous instances of the dataset do not belong to DDoS category so we have separated only the DDoS packets from the dataset using the selected features. Finally, the dataset has been prepared and named as KDD DDoS dataset by considering the selected DDoS packets and normal packets. This KDD DDoS dataset has been discretized using discretize tool in weka for getting better performance. Finally, this discretize dataset has been applied on some commonly used (Naive Bayes, Bayes Net, Decision Table, J48 and Random Forest) classifiers for determining the detection rate of the classifiers. 10 fold cross validation has been used here for measuring the robustness of the system. To measure the efficiency of our hybrid feature selection method, we have also applied the same set of classifiers on the NSL KDD dataset, where it gives the best anomaly detection rate of 99.72% and average detection rate 98.47% similarly, we have applied the same set of classifiers on NSL DDoS dataset and obtain the average DDoS detection of 99.01% and the best DDoS detection rate of 99.86%. In order to compare the performance of our proposed hybrid method, we have also applied the existing feature selection methods and measured the detection rate using the same set of classifiers. Finally, we have seen that our hybrid approach for detecting the DDoS attack gives the best detection rate compared to some existing methods.
  • Fractal image compression with quadtree partitioning and a new fast classification strategy

    Nandi U., Santra S., Mandal J.K., Nandi S.

    Conference paper, Proceedings of the 2015 3rd International Conference on Computer, Communication, Control and Information Technology, C3IT 2015, 2015, DOI Link

    View abstract ⏷

    In this paper, a new fast classification strategy is proposed for fractal image compression with quadtree partitioning technique. The scheme significantly reduces the number of mean square error (MSE) computations during encoding of images. Performance in terms of compression ratios, compression time and PSNR of the fractal image compression with existing and proposed classification strategy are compared. Both techniques use quadtree partitioning scheme. The proposed classification strategy reduces the compression time significantly of the fractal image compression technique maintaining compression ratio and PSNR almost same with its counterpart.
Contact Details

suman.n@srmap.edu.in

Scholars